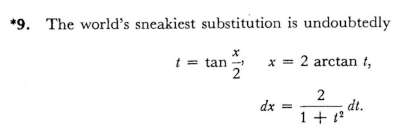Making peace with the projective plane

In my newsletter I give an introduction to the latest few posts and occasionally give some additional commentary. In my latest newsletter I wrote

Projective space and homogeneous coordinates seemed like arbitrary abstractions when I was a student because they were presented without any motivation. Much later I came to realize that they’re natural, almost inevitable. Exceptional cases and hand-wavy references to objects “at infinity” go away when moving to projective space.

My mathematics education was very top-down: abstractions first, specifics later (if ever). I was OK with that for a while, until I hit my abstraction tolerance sometime in grad school. Now I would advocate more of a bottom-up approach, motivating abstractions first rather than presenting them as a fait accompli.

The first time I saw the projective plane was probably in a topology class where someone said you could construct the plane by starting with a square and gluing opposite edges in a physically impossible way. This seemed like a gimmick, a way to construct a non-orientable manifold but not anything practical. Another construction is to say the projective plane is an ordinary sphere with antipodal points identified. I found that a little more satisfying, but it still unmotivated.

What I would have appreciated was someone saying that the projective plane was invented to make geometry more elegant by eliminating exceptional cases and making rigorous the idea of things “at infinity.” For example, geometric calculations often have to treat vertical lines specially, but vertical lines are not special in projective geometry.

You could start by saying we’re going to represent points in the plane not simply as (x, y) but as (x, y, 1) and use (x, y, 0) for the point at infinity in the direction (x, y). That may seem like a hack, but it’s certainly motivated. It’s exactly the sort of thing a graphics programmer would do. In fact, I imagine many programmers have done just that, independently bumping into projective geometry.

After having introduced this extra coordinate, it’s natural to ask what would it mean if the last coordinate were something other than 0 or 1. You’ll quickly run into this when you start doing calculations on these extended coordinates. You could have a rule that you always normalize by dividing by the last coordinate, if it’s not zero, and then you have essentially discovered homogeneous coordinates. (Update; I develop this idea in more detail in the next post.)

You’ll see something like the approach above in elliptic curve cryptography. Programmers wanting to implement encryption algorithms are thinking concretely in terms of (x, y) points, until they have to worry about a mysterious “point at infinity” and handle it correctly. Then homogenous coordinates appear as a tool for getting out of a bind.

***

I thought about titling this post something like “Dr. Strangelove, or: How I Learned to Stop Worrying and and Love the Projective Plane” but I wasn’t sure how well that would go over. I doubt many readers have seen the 1964 movie this is alluding to, but the trope “How I Learned to Stop Worrying and Love …” is more widely known than the movie itself.

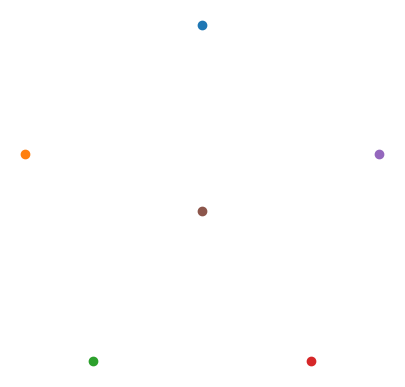
A unified view of poles and polars

I wrote several posts on poles and polars a few days ago. First, I wrote about the dual of a spherical triangle, called the polar triangle. Then I wrote about poles and polars in plane geometry and briefly mentioned the extension to projective geometry.

Poles and polars are a little awkward in the plane because you have to pay attention to special cases. Poles and polars are relative to a conic section, and are defined/computed differently depending on whether you’re taking the dual with respect to an ellipse, parabola, or hyperbola. Also, the polar of the center of a conic section isn’t defined.

Projective space

If you move from the Euclidean plane to the projective plane, the exceptions go away, though it may not seem so if you’re talking about points at infinity or lines at infinity. If you fully commit to working in projective space, there aren’t any hand-wavy points or lines “at infinity.” There’s not even a distinction between ellipses, parabolas, and hyperbolas.

There’s no such thing as a free lunch, and the cost of this elegant unification is moving to a bigger geometric space with a different coordinate system. Instead of working in the Euclidean spaces R² or Rn, we work in Pn over a field F which could be R but doesn’t need to be [1].

The coordinates on Pn are homogeneous coordinates, (n + 1)-tuples of field elements, not all equal to zero, with two (n + 1)-tuples representing the same point if they are proportional, i.e. one is a non-zero multiple of the other.

We can embed Rn in Pn by adding an extra coordinate on the end, set equal to 1. You could think of this extra coordinate as a switch, set to 1 for finite points and set to 0 for infinite points. But this distinction between finite and infinite points is an artifact of the embedding, not a property of Pn: there are no special points in Pn. A point that is “at infinity” in one embedding of Rn in Pn need not be in another embedding.

Poles and polars

Once you accept the need to work in homogeneous coordinates, everything becomes simple and consistent.

A quadric (a conic section when n = 2) is the set of points

{x : xᵀAx = 0}

where A is a non-singular (n + 1) by (n + 1) symmetric matrix over F.

The polar of a point p is the hyperplane

{x : pᵀAx = 0}

and the pole of a hyperplane

H = {x : uᵀx = 0}

is the point

p = A−1 u.

Notice there’s no mention of “infinity” in this section. All the calculations take place in the field F with no points at infinity added.

[1] The only requirement is that the field F cannot have characteristic 2. So F could be the reals, the rationals, the complex numbers, etc. F could even be a finite field as long as the number of elements in F is not a power of 2.

Locally everywhere does not imply everywhere

A couple days ago, Levent Alpöge, a mathematician working at Anthropic, discovered a counterexample to the Jacobian conjecture using Claude Fable 5.

I was curious whether most mathematicians were trying to prove or disprove the conjecture, so I asked Claude.

Before a counterexample to the Jacobian conjecture was found, did most mathematicians believe it was true or false?

Claude’s response was

The premise of this question isn’t quite right — no counterexample to the Jacobian conjecture has been found. It remains an open problem in mathematics: no one has proven it true, and no one has found a counterexample disproving it. … If you encountered a claim that a counterexample was found, do you have a source for that? I’d be happy to look into it, since that would actually be a major result in algebraic geometry if true.

Of course Claude doesn’t know that it solved the conjecture. It didn’t even solve the conjecture. It was an inanimate tool in the hand of a mathematician, just like a piece of chalk or a dry erase marker.

The middle part of Claude’s response was that mathematicians are (were) divided on whether the conjecture is true. So it was not like the Riemann hypothesis, which most people believe to be true, or the P = NP conjecture, which most people believe to be false.

Now what is the Jacobian conjecture? It says that a polynomial function from ℝn to ℝn with constant, non-zero Jacobian determinant has a polynomial inverse. (The conjecture was stated more generally for fields of characteristic 0, in which the derivatives defining the Jacobian would have to be defined algebraically, not in terms of limits.)

Alpöge came up with a counterexample, a polynomial function from ℝ³ to ℝ³ with constant Jacobian determinant −2. The function is

\begin{align*}F(x,y,z)={}\bigl(~\!& z (1+xy)^3 + y^2 (1+xy) (4+3xy),\\ &y + 3x(1+xy)^2 z + 3xy^2 (4+3xy), \\ &2x - 3x^2 y - x^3 z ~\!\bigr).\end{align*}

It’s a tedious but simple calculus exercise to show that the determinant equals −2 everywhere. The inverse function theorem says that a function is locally invertible at any point where the Jacobian determinant is non-zero, so Alpöge’s function is locally invertible everywhere.

However, the function takes on some values more than once. For example, (0, 0, −1/4) and (1, −3/2, 13/2) both map to (−1/4, 0, 0). Therefore the function is not invertible globally. So not only does the function not have a polynomial inverse, it doesn’t have an inverse even if you allow non-polynomial functions.

Alpöge’s counterexample disproves the Jacobian conjecture for n = 3. It can trivially be extended to all n > 3 by defining the function to be Alpöge’s function for three variables and the identity for the rest. The conjecture remains open for n = 2.

Solution to a problem of Erdős

How many ways can you select six points in the plane so that every subset of three points forms the vertices of an isosceles triangle? This is a question asked by Erdős and recently resolved.

One solution is to choose the five vertices of a regular pentagon and the center.

Erdos pentagon

It’s easy to verify that this is a solution. The much harder part is to show that this is the only solution.

A uniqueness proof was published on arXiv last Friday: A note on Erdős’s mysterious remark by Zoltán Kovács.

More Erdős-related posts

The world’s sneakiest substitution

Something that seems like an isolated trick may turn out to be much more important. This is the case with a change of variables discovered by Karl Weierstrass.

Every calculus student learns a handful of standard techniques: u-substitutions, partial fractions, integration by parts, and trig substitutions. Then there is one more technique that is like something off a secret menu, something know only to the cognoscenti: Weierstrass’ t = tan(x/2) trick [1]. Michael Spivak called this “the world’s sneakiest substitution.”

The world's sneakiest substitution is undoubtedly t = tan(x/2), x = 2 arctan t, dx = 2 dt / (1 + t^2)

This was on page 325 of the first edition of Spivak’s Calculus, page 360 of the second edition.

This innocent but apparently unmotivated change of variables has the following magical consequences:

  • sin(x) = 2t/(1 + t2)
  • cos(x) = (1 – t2) / (1 + t2)
  • dx = 2 dt/(1 + t2).

This means that the trick can convert an integral containing any rational combination of trig functions into one involving only rational functions, which then can (in principle) be integrated in closed form using partial fractions. It’s the key that unlocks all trig integrals.

However, this is not as practical as it sounds. You may get a high-degree rational function, and while in theory the rational function can be integrated using partial fractions, the decomposition may be tedious if not impossible. Still, it’s interesting that a single trick reduces one large class of integration problems to another.

Now let’s leave integration behind. The equations above say that as t varies, the functions 2t/(1 + t2) and (1 – t2) / (1 + t2) take on all the values that sin(x) and cos(x) do. This means, for example, that you can draw a circle using graphics hardware that does not support sines and cosines. In theory the range of t would have to be infinite, but in practice the range would only have to be large enough to fill in the right pixels.

If we can parameterize a circle with rational functions, what else can we parameterize this way? It turns out, for example, that elliptic curves do not have rational parameterizations. This question is its own niche of algebraic geometry. I don’t know the history here, but it’s plausible some of this math was motivated by wondering what else could be done along the lines of Weierstrass’ trick.

[1] When I’ve mentioned this trick before, some have told me this was a routine part of their course. That was not my experience, either as a student or as an instructor. As a freshman I learned the trick from a friend who was the best of our cohort at integration, someone who would have done well at an integration bee if we’d had one. I felt I’d been let in on a secret.

Certifying that a system of polynomial equations has no solution

It’s usually easier to show that a problem has a solution than to show that it does not have a solution.

Analogy with prime numbers

Showing that a number is prime amounts to saying that the problem of finding nontrivial factors has no solution. How could you convince a skeptic that a large number N is prime? If N is small enough that it is possible to divide N by every integer less than √N then that would do it, but that’s not practical if, say, N has 100 digits. Nevertheless there is a way.

Primality certificates are a way to prove that a number is prime, just as demonstrating a factor is a way to prove that a number is not prime. A primality certificate is a set of calculations a skeptic can run that will prove that the number in question is prime. Producing such a certificate takes a lot of computation, but verifying the certificate does not.

I wrote several articles on primality certificates at the beginning of this year. For example, here is one on Pratt certificates and here is one on elliptic curve certificates.

Analogy with convex optimization

Claiming that you’ve found the maximum value of some function amounts to saying a certain problem has no solution, namely the problem of finding where the function takes on a larger value than the one you claim is optimal. How can you convince a skeptic that you’ve really found the maximum?

You could say “I’ve tried really hard. Here’s a list of things I’ve tried, and see, none of them give a larger value.” Sometimes that’s all you can do. But for convex optimization problems, you can produce a certificate that a skeptic could evaluate that proves that your solution is optimal. More on that here.

Systems of polynomial equations

Now suppose you have a system of polynomial equations. If you’re able to find a solution, then this solution is its own certificate. Want to prove that supposed solution actually is a solution? Plug it in and see.

But how do you prove that you haven’t overlooked any possibilities and there simply isn’t a solution to be found? Once again there is a kind of certificate.

Suppose you have a system of m polynomial equations in n complex variables.

\begin{align*} f_1(z_1, z_2, z_3, \ldots, z_n) &= 0 \\ f_2(z_1, z_2, z_3, \ldots, z_n) &= 0 \\ f_3(z_1, z_2, z_3, \ldots, z_n) &= 0 \\ &\cdots \\ f_m(z_1, z_2, z_3, \ldots, z_n) &= 0 \\ \end{align*}

The system of equations has a solution if and only if the algebraic variety generated by the f‘s is non-empty.

If we can find a polynomial combination of the f‘s that equals 1, i.e. we can find g1 through gm such that

g_1 f_1 + g_2 f_2 + g_3 f_3 + \cdots + g_mf_m = 1

then the variety generated by the f‘s is empty. Such a polynomial combination would be a certificate that the system of equations has no common solution, a certificate of infeasibility. There is an algorithm for finding this polynomial combination, the extended Buchberger algorithm, an analog of the extended Euclidean algorithm.

There is a corresponding theorem for polynomials of a real variable, the so-called positivstellensatz, but it is a little more complicated. The name “complex numbers” is unfortunate because passing to “complex” numbers often simplifies problems.

Related posts

An algebraic superegg

One year ago I wrote about a variant of the squircle that is quantitatively close to the customary definition but that has nicer algebraic properties.

That post used the term p-squircle for the usual squircle with equation

|x|^p + |y|^p = 1

where p > 2, and the term s-squircle for the variation with equation

x^2 + y^2 = s^2 x^2 y^2 + 1

where s is between 0 and 1. When p = 2 or s = 0 we get a circle. As p goes to infinity or s = 1 we get a square.

Now the superegg is formed by rotating a squircle about an axis. To match the orientation in the posts I’ve written about supereggs, replace y with z above and rotate about the z-axis. We will also introduce a scaling factor h, dividing z by h.

The superegg analog of the s-squircle would have equation

x^2 + y^2 + (z/h)^2 = s^2 (x^2 + y^2) (z/h)^2 + 1

The s-superegg is much easier to work with (for some tasks) than the p-superegg with equation

\left(\sqrt{x^2 + y^2}\right)^p + |z/h|^p = 1

because the former is a polynomial equation and the latter is transcendental (unless p is an even integer). The s-superegg is an algebraic variety while the p-superegg is not in general.

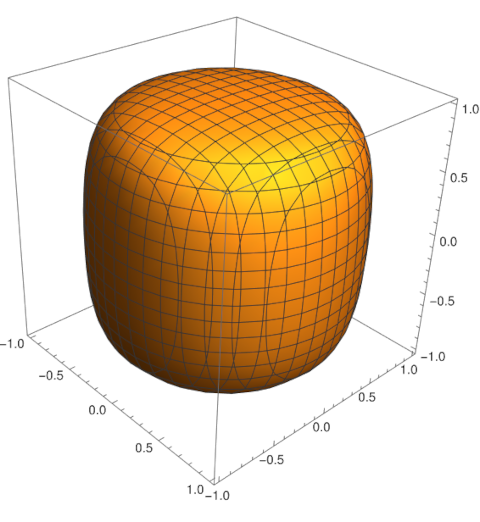
Here’s a plot with s = 0.9 and h = 1.

This plot was made with the following Mathematica code.

    ContourPlot3D[
        x^2 + y^2 + z^2 == 0.9^2 (x^2 + y^2) z^2 + 1, 
        {x, -1, 1}, {y, -1, 1}, {z, -1, 1}]

Yesterday I said that the p-superegg is stable for all p > 2 because the curvature at the bottom is 0. This means the center of curvature is at infinity, which is above the center of mass.

The s-superegg has positive curvature at the bottom for all 0 < s < 1 and so the center of curvature is finite. As s increases, the superegg becomes more like a cylinder and the center of curvature increases without bound. So the s-superegg will be stable for sufficiently large s.

I calculate the center of curvature in the next post.

Related posts

Nonlinear algebra

What is nonlinear algebra?

Negations are tricky. They may be the largest source of bugs in database queries. You have to carefully think about what exactly are you negating.

Any time you see “non-” attached to something, you have to ask what the context is in which the negation takes place. For example, if you hear someone say “non polar bear,” do they mean a (non-polar) bear, i.e. any bear besides a polar bear, such as a grizzly bear? Or do they mean non-(polar bear), i.e. anything that isn’t a polar bear, such as a giraffe or an espresso machine?

Another subtlety is whether “non” means “definitely not” or “not necessarily.” I specialized in nonlinear PDEs in grad school, and “nonlinear” always meant “not necessarily linear.” I don’t recall ever seeing a theorem that required an operator to not be linear, only theorems that did not require operators to necessarily be linear.

With that introduction, what could nonlinear algebra mean? To many people, it would mean working with equations that contain nonlinear terms, such as solving sin(x) = 2x. The sine function is certainly nonlinear, but it’s not the kind of function algebraists are usually interested in.

To a large extent, the algebraist’s universe consists of polynomials. In that context, “nonlinear” means “polynomials that are not necessarily linear.” So things that are nonlinear in the sense that x³ is nonlinear, not in the sense that sin(x) is nonlinear.

If you think of linear algebra as the math surrounding the solution of systems of linear equations, nonlinear algebra is the math surrounding the solution of systems of polynomial equations. Note that this uses “non” in the “not necessarily” sense: polynomials that are not necessarily linear. Linearity is not assumed, but it’s not excluded either.

You might be thinking “isn’t that just algebraic geometry?” if you’re familiar with algebraic geometry. Strictly speaking the answer is yes, but there’s a difference in connotation if not denotation.

Nonlinear algebra, at least how the term has been used recently, means the application-motivated study of ways to solve polynomial equations. As a recent book review puts it,

Nonlinear algebra’s focus is on computation and applications, and the theoretical results that need to be developed accordingly. Michalek and Sturmfels explain that this name is not just a rebranding of algebraic geometry but that it is intended to capture this focus, and to be more friendly to applied mathematicians, questioning the historic boundaries between pure and applied mathematics.

I like the term nonlinear algebra. Algebraic geometry is a vast subject, and there needs to be a term that distinguishes solving polynomial equations for applications from studying some of the most esoteric math out there. One could argue that the latter is ultimately the proper theory of the former, but a lot of people don’t have the time or abstraction tolerance for that.

The term nonlinear algebra may be better than applied algebraic geometry because the latter could imply that the goal is to master the entire edifice of algebraic geometry and look for applications. Nonlinear algebra implies it is for someone looking to learn math as immediately useful for solving nonlinear equations as linear algebra is for solving linear equations.

Related posts

Rational Trigonometry

Rational trigonometry is a very different way of looking at geometry. At its core are two key ideas. First, instead of distance, do all your calculations in terms of quadrance, which is distance squared. Second, instead of using angles to measure the separation between lines, use spread., which turns out to be the square of the sine of the angle [1].

What’s the point of these two changes? Quadrance and spread can be computed purely algebraically in terms of point coordinates. No square roots, no sines, and no cosines.

The word “rational” in rational trigonometry enters in two ways. The spread of two lines is a rational function of their coordinate descriptions, i.e. the ratio of polynomials. Also, if the coordinates of a set of points are rational numbers, so are the quadrances and spreads.

I became interested in rational trigonometry when I was working on a project to formally verify drone collision avoidance software. Because all calculations are purely algebraic, involving no transcendental functions, theorems are easier to prove.

Rational trigonometry is such a departure from the conventional approach—trig without trig functions!—you have to ask whether it has advantages rather than simply being novel for the sake of being novel. I mentioned one advantage above, namely easier formal theorem proving, but this is a fairly esoteric application.

Another advantage is accuracy. Because a computer can carry out rational arithmetic exactly, rational trigonometry applied to rational points yields exact results. No need to be concerned about the complications of floating point numbers.

A less obvious advantage is that the theory of rational trigonometry is independent of the underlying field [2]. You can work over the rational numbers, but you don’t need to. You could work over real or complex numbers, or even finite fields. Because you don’t take square roots, you can work over fields that don’t necessarily have square roots. If you’re working with integers modulo a prime, half of your numbers have no square root and the other half have two square roots. More on that here.

Why would you want to do geometry over finite fields? Finite fields are important in applications: error-correcting codes, cryptography, signal processing, combinatorics, etc. And by thinking of problems involving finite fields as geometry problems, you can carry your highly developed intuition for plane geometry into a less familiar setting. You can forget for a while that you’re working over a finite field and proceed as you ordinarily would if you were working over real numbers, then check your work to make sure you didn’t do anything that is only valid over real numbers.

[1] Expressing spread in terms of sine gives a correspondence between rational and classical trigonometry, but it is not a definition. Spread is defined as the ratio of certain quadrances. It is not necessary to first compute a sine, and indeed rational trigonometry extends to contexts where it is not possible to define a sine.

[2] Rational trig is not entirely independent of field. It requires that fields not have characteristic 2, fields where 1 + 1 ≠ 0. This rules out finite fields of order 2n.

Why determinants with columns of ones?

Geometric equations often involve a determinant with a column of 1s. For example, the equation of a line through two points:

\begin{vmatrix} x & y & 1 \\ x_1 & y_1 & 1 \\ x_2 & y_2 & 1 \\ \end{vmatrix} = 0

The equation of a circle through three points:

\begin{vmatrix} x^2 + y^2 & x & y & 1 \\ x_1^2 + y_1^2 & x_1 & y_1 & 1 \\ x_2^2 + y_2^2 & x_2 & y_2 & 1 \\ x_3^2 + y_3^2 & x_3 & y_3 & 1 \\ \end{vmatrix} = 0

The equation of a general conic section through five points

\begin{vmatrix} x^2 & xy & y^2 & x & y & 1 \\ x_1^2 & x_1 y_1 & y_1^2 & x_1 & y_1 & 1 \\ x_2^2 & x_2 y_2 & y_2^2 & x_2 & y_2 & 1 \\ x_3^2 & x_3 y_3 & y_3^2 & x_3 & y_3 & 1 \\ x_4^2 & x_4 y_4 & y_4^2 & x_4 & y_4 & 1 \\ x_5^2 & x_5 y_5 & y_5^2 & x_5 & y_5 & 1 \\ \end{vmatrix} = 0

The equation of a Mobius (bilinear) transformation sending z1, z2, and z3 to w1, w2, and w3:

\begin{vmatrix} 
z & w & zw  & 1\\
z_1 & w_1 & z_1w_1 & 1 \\
z_2 & w_2 & z_2w_2 & 1 \\
z_3 & w_3 & z_3w_3 & 1 \\ 
\end{vmatrix} = 0

Why all the determinants and why all the 1s?

When you see a determinant equal to zero, you immediately think of matrix rows or columns being linearly dependent. But in the examples above it isn’t the Cartesian coordinates that are linearly dependent but projective coordinates that are dependent.

The 1s are in the last column, though they need not be, as a clue as to where they came from. You could permute the rows and columns any way you like and the determinant would still be zero. The 1s are in the last column because you can take Cartesian coordinates into projective coordinates by adding a 1 at the end.

This 1 is sort of a silent partner, and can be ignored much of the time. But the last projective coordinate is critical when it’s necessary to be rigorous about points at infinity. The examples above are interesting because they are an application of homogeneous coordinates when there’s no concern about points at infinity.

Related posts