How the eMudrha certificate debacle might have happened

You may have seen references to a password being the number 4. There are countless allusions to this online, but they don’t give the context.

As I mentioned in an earlier post, eMudrha was using the numbers 4, 56, 115, 155, 156, 230, and 237 as secret keys. I haven’t seen details of how this happened, but in this post I’ll give a plausible account of how it might have happened, what someone could have done to produce those results. I’m not trying to do forensic analysis on this specific incident, just exploring what someone might do.

eMudrha was using the NIST elliptic curve P-384, and a secret key should be a random number chosen between 1 and 2384. That upper bound isn’t exactly correct, but it’s close. See this post if you want to know the exact number.

Someone might have chosen numbers up to 384 rather than 2384 out of ignorance. Or they might done so by a typo. Maybe they generated a random value that might have been larger than 2384 and then intended to reduce the number mod 2384, but instead of typing

% 2**384

they typed

% 384

It seems more likely, however, that somehow someone took one byte of a random value because all the keys are less than 28 = 256.

The probability of choosing seven numbers from 1 to 384 and all being less than or equal to 237 is around 0.034. But the same probability for numbers chosen between 1 and 256 is about 0.60.

Backdoors, Incompetence, and Elliptic Curves

The NIST elliptic curves have been in the news twice lately. A few days ago Anthropic posted a paper on the NIST curve seeds that I wrote about here. Now the curves are in the news again, this time over broken certificates.

My post a few days ago was about the possibility that the NSA had added a backdoor to the NIST curves. Anthropic researchers showed that this wasn’t the case. The NSA had not been able to defend how the curve seeds were chosen because they forgot, but researchers from Anthropic were able to reverse engineer the source of the seeds.

So apparently the NIST curves do not have a backdoor, but as with all encryption, the Achilles heel is human error. eMudrha was using the NIST curve P-384  with extremely small keys: 4, 56, 115, 155, 156, 230, and 237. To understand why this is a problem, I’ll briefly describe how elliptic curve cryptography works.

P-384 is an elliptic curve designed by NIST, with input from the NSA, for use in cryptography. The curve has on the order of 2384 points because the base field is the integers mod

p = 2384 − 2128 − 296 + 232 − 1,

a 384-bit prime number. Given a basepoint b on the curve and an exponent e, it is practically impossible to recover e from be. That’s the discrete logarithm problem [1], the basis for the security of elliptic curve cryptography. If and when cryptographically relevant quantum computers arrive, the discrete logarithm problem will be solvable and elliptic curve cryptography will be broken.

Until the advent of quantum computing, elliptic curve cryptography is presumably safe, unless someone does something negligent, such as using a tiny value of e like 4.

If e is chosen at random from a group with on the order of 2384 elements, you cannot recover e from be without brute force. But apparently someone said

Let’s see. Is e = 1? Is it 2? Is it 3? Is it 4? Why yes: e = 4.

Ordinarily this would be hopeless. You can’t just try 2384 exponents. But someone thought to test whether the keys were horrifically bad, and they were right.


[1] The exponentiation here is not over the integers, or over the integers mod p. It’s over the group structure of the elliptic curve, and that is what makes it hard to compute the discrete logarithm.

Cloud of suspicion lifted from NIST curves

NIST published a set of elliptic curves for cryptography in 2000. The seeds for the curves were supplied by the NSA, and cryptographers suspected the agency may have installed backdoors in the curves. And not without reason: the NSA did insert a backdoor in the Dual_EC_DRBG random number generator.

Two days ago researchers at Anthropic [1] showed that the NIST curves were not seeded with a backdoor. The rest of this post will give the background necessary to appreciate this result.


The security of elliptic curve cryptography depends on the difficult of solving the discrete logarithm problem. In the context of elliptic curve arithmetic, the analog of exponentiation is easy but the analog of taking logarithms is hard.

In general it’s not practical to compute discrete logarithms over large elliptic curves. But it could be easy for someone with inside information to compute discrete logarithms if something about the curve was not “general.”

Specifically, the NIST curves have the form

y² = x³ − 3x + b (mod p)

for various values of p [2], and the suspicion regards the choice of b. For nearly all values of b encryption over the elliptic curve should be secure, as far as we know, but in principle someone could engineer values of b to weaken the encryption.

So where did the b‘s come from? Were they chosen in good faith?

Concern over the choice of seeds, the b‘s, grew following the Snowden revelations. Daniel J. Bernstein emailed Jerry Solinas of the NSA on September 6, 2014 asking where the seeds had come from. Solinas replied in subsequent emails. He said the seeds were generated by hashing the ASCII representation of a humorous English message, but he could no longer remember the exact message or the precise hashing procedure.

On October 5, 2023 Philippo Valsorda announced a bounty for reverse engineering the origin of the NIST elliptic curve seeds. Two days ago researchers from Anthropic claimed the bounty. Valsorda verified the results and awarded the prize. It turns out Solinas found the curve seeds in good faith, but his memory had faded over the years since the curves were published. We now know he used a date, not a phrase, as part of the process of constructing the seeds.

The NIST curves have some nice properties, such as enabling some clever tricks for arithmetic in their base fields. But adoption of the curves has been held back over suspicion regarding their origin. Now the curves have been exhonorated. As Valdorda notes

… this nicely completes the “rehabilitation arc” of NIST elliptic curve cryptography, which I would now personally recommend over Curve25519/Ed25519/X25519. Just in time for them to be retired in favor of post-quantum signatures.

Related posts

[1] This does not imply that LLMs are necessarily a threat to encryption. The search for the NIST seeds required a lot of brute force. Some cleverness was required in order to come up with possibilities to check by brute force, but even that is sorta brute force at a higher level of abstraction. There has been speculation that labs are looking for weaknesses in cryptographic primitives and protocols, but that’s a different matter than searching for seeds.

[2] The curves P-192, P-224, P-256, P-384, and P-521 are built over the field of integers mod p, where the number of bits in p corresponds to the number in the name. The P-192 curve, for example, has as its base field the integers mod 2192 − 264 − 1, a 192-bit prime.

New RSA number factored

Eric Lu announced on X today that he has factored RSA-260, a number N with 260 digits (862 bits) that is the product of two large primes [1].

RSA numbers are challenge problems posed to gauge the security of RSA encryption, which rests on the difficulty of factoring large numbers [2]. The naming scheme is confusing because RSA-n might have n digits or n bits. For example, RSA-768 is smaller than RSA-260 because the former has 768 bits and the latter has 260 digits.

RSA-260 is the largest RSA number factored so far. What does the news of its factorization say about the security of RSA?

Based on equations here, an RSA key with 862 bits would have a security level of 74 bits, i.e. the same security level as symmetric encryption with a 74-bit key. The minimum recommended RSA key size now is 2048 bits, which has a security level of 107 bits.

Security levels are on a logarithmic scale: each additional bit of security doubles the effort required to break the encryption by brute force. So breaking a 2048-bit RSA key would take 234, roughly 1010, times more effort than factoring RSA-260. All this depends on numerous assumptions, such as the state of factorization algorithms and the non-existence of CRQC [3].

Update: A week after the initial announcement, Eric Lu released an article explaining how he factored RSA-260. He says “In total, I estimate that this factorization cost about 4,900 GPU-days, or 13.5 GPU-years, which is about $400k at current market prices.”

Related posts

[1] N = pq = 22112825529529666435281085255026230927612089502470015394413748319128822941402001986512729726569746599085900330031400051170742204560859276357953757185954298838958709229238491006703034124620545784566413664540684214361293017694020846391065875914794251435144458199

p = 4397328654844826923795068102505872571721883526553349659561256924505973939597593482272505698004801207988043088656411102133523080581

q = 5028695206842569864686141618253083416610081090075366674776775706538324961364412200138116378509733307971876652984898985905923678379

[2] The ability to efficiently factor large primes would break RSA. It’s possible that there’s a way to break RSA without being able to factor large numbers. More on that here.

[3] Cryptographically-relevant quantum computer. Quantum computers exist, but so far they’re cryptographically irrelevant. So far quantum computers cannot factor 21 without cheating.

Cryptographic Keys and Decks of Cards

The previous post looked at the idea of storing a cryptographic key in the order of a deck of cards. A deck of 52 cards can store 225 bits of data because

⌊log2(52!)⌋ = 225.

Here ⌊x⌋ is x rounded down to the nearest integer.

If we want to store bigger keys, we’re going to need a bigger deck of cards.

Bitcoin

A Bitcoin key has 256 bits, which would require a deck of 58 cards. There is a card game called Zwicker that uses a deck of 58 cards, the usual 52 cards plus six jokers. So you could store a Bitcoin key in the permutation of a Zwicker deck.

You could also use a deck of 52 cards, plus 2 jokers, if you also consider orientation. 30 cards are rotationally symmetric, 22 are not, and neither are jokers. So, including two asymmetric jokers, you could add 24 additional bits. Permutations of a 54 card deck can encode 237 bits, and with 24 orientation bits, this is a total of 261 bits.

RSA

RSA key sizes vary, but 2048 and 3072 are common. A 2048-bit key would require a deck of 301 cards. Casinos often use a shoe of 312 cards, combining six decks of 52 cards, to deal Baccarat or Blackjack. However, casinos combine identical decks. If you were to combine six unique decks, you could store a 2048-bit key.

Storing a 3072-bit key would require a deck of 422 cards. You could make a deck of 432 cards by combining 8 distinguishable packs of 54 cards (52 + 2 jokers).

ML-KEM

ML-KEM is a proposed quantum-resistant replacement for RSA. As with RSA, key sizes for ML-KEM vary, the smallest being ML-KEM-512 with a key size of 1632 bytes, which equals 13056 bits. This would require a deck of 1442 cards. You could combine 28 distinct packs of 52 cards, but that’s unwieldy.

This illustrates one of the difficult trade-offs with post-quantum cryptography: key sizes are much bigger. If you wanted to create a deck of 1442 cards, you’d probably want to make your “cards” something other than standard playing cards. You’d want to use permutations of something else.

Verification

The following Python code verifies the calculations above.

from math import log2, factorial, floor

def capacity(cards):
    return floor(log2(factorial(cards)))

def verify(bits, cards):
    return capacity(cards) >= bits and capacity(cards-1) < bits

print(verify(237, 54))
print(verify(256, 58))
print(verify(2048, 301))
print(verify(3072, 422))
print(verify(1632*8, 1442))

For more on how I came up with the deck sizes, see the next post on computing the inverse factorial.

Hiding data in permutations

The latest issue of Paged Out! has an article by Stephen Hewitt “An off-line backup of your cryptographic key using playing cards.” The idea is to use a deck of 52 to store a 128-bit cryptographic key. To erase the key, shuffle the deck. Hewitt gives his algorithm for embedding a key, one that can be carried out manually but isn’t maximally efficient.

You could store a 225-bit key as a permutation of 52 cards because

log2(52!) = 225.581.

But then how would you number permutations so you could go from a number to a particular permutation and later decode the permutation to a number? Is this even practical? For a small number n, you could encode a number k < n by enumerating the first k permutations of a set of n items, and you could decode by enumerating permutations until you find the one you have. But this is completely impractical for large n, such as n = 52.

The process of mapping permutation to an integer is called ranking, and the mapping from an integer to a permutation is called unranking. How efficiently can rankings and unrankings be calculated?

Let n be the number of symbols being permuted. Then there are simple algorithms for ranking and unranking with respect to lexicographical order that have complexity O(n²) and more sophisticated algorithms that have complexity O(n log n). There are also O(n) algorithms that do not preserve lexicographical order.

The Permutations class in SymPy has methods unrank_lex and rank to unrank and rank permutations according to lexicographical order.

The notation the Permutations class uses requires a little explanation. For example, suppose we unrank 2026.

>>> from sympy.combinatorics import Permutation
>>> Permutation.unrank_lex(52, 2026)
Permutation(45, 47, 51, 48, 46, 50)

The output is not a full list of 52 numbers in permuted order; it is only a cycle. The notation refers to the permutation that sends 45 to 47, 47 to 51, …, 50 to 45 and leaves everything else fixed.

If we rank the permutation given above, we get 2026 back.

>>> Permutation.rank(Permutation(45, 47, 51, 48, 46, 50))
2026

Note that we didn’t say how many elements (45, 47, 51, 48, 46, 50) is a permutation of. Because of lexicographical order, the rank would be the same whether we viewed this as a permutation of 52 objects or of more objects.

Now let’s do something larger. Let’s generate a 220-bit number and encode it as a permutation.

>>> n = random.getrandbits(225)
>>> a = Permutation.unrank_lex(52, n)
>>> n
40234719030664563684489051530416964877785781669439875437823431388841
>>> a
Permutation(0, 25, 32, 15, 8, 28)(1, 48, 34, 14, 10, 51, 38, 31, 21, 5, 42, 47, 29, 26, 46, 30, 50, 49, 37, 22, 18, 23)(2, 45, 17, 20, 36, 40, 11, 4, 7, 41, 33, 3, 43, 44, 19, 16, 35, 39, 12, 6, 9)
>>> Permutation.rank(a) == n
True

Now just for fun, let’s display the permutation above applied to a standard (French) deck of 52 cards. As explained here, symbols associated with these cards have a range of Unicode values. By printing these values, we can visualize the permuted deck.
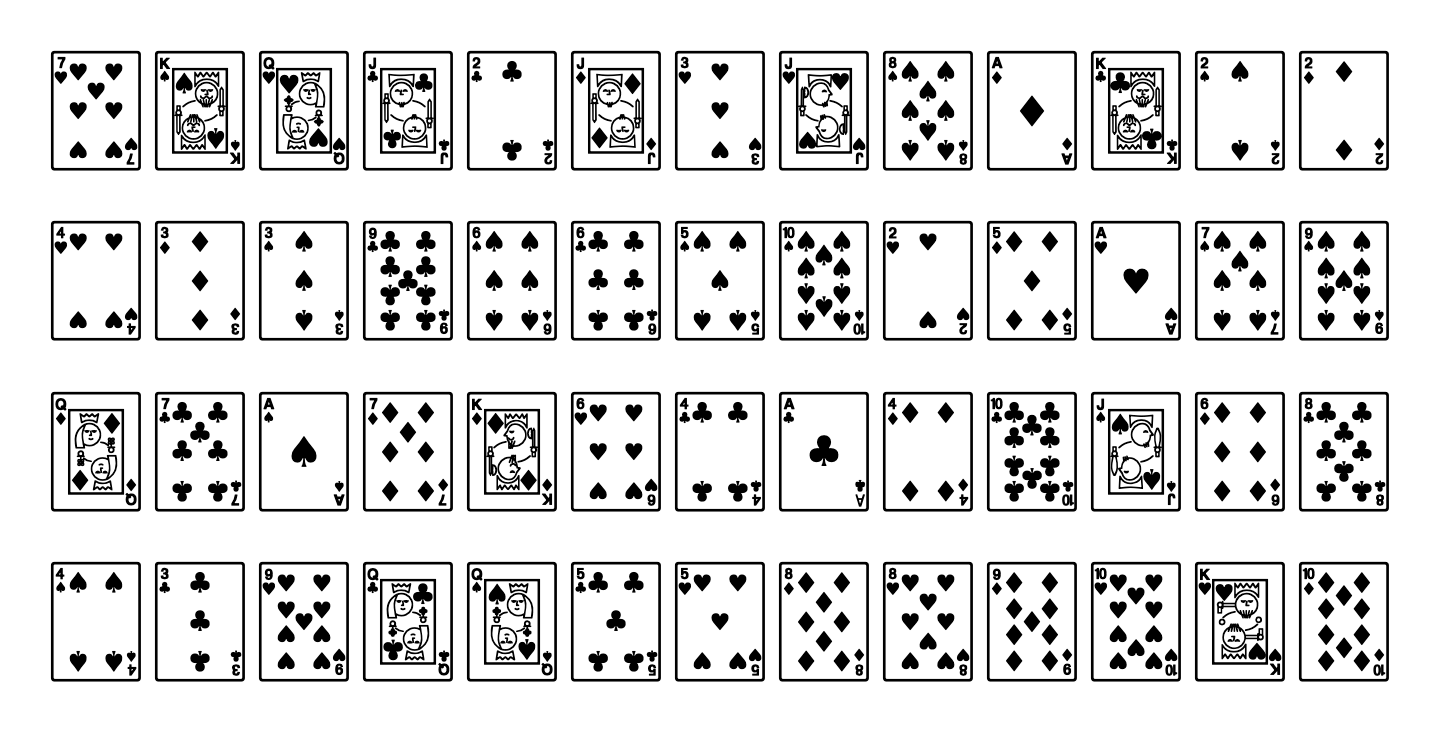
Here’s the code that made the image above.

spades = list(range(0x1F0A1, 0x1F0AF))
spades.remove(0x1F0AC) # take out the knight
cards = [s + 16*i for s in spades for i in range(4)]

a = Permutation.unrank_lex(52, n)
p = a(cards)

for i in range(4):
    for j in range(13):
        print(chr(p[13*i + j]), end="")
    print()

The code above is plenty fast, but Permutation has methods rank_nonlex and unrank_nonlex that run in O(n) time, which could be useful for n much larger than 52.

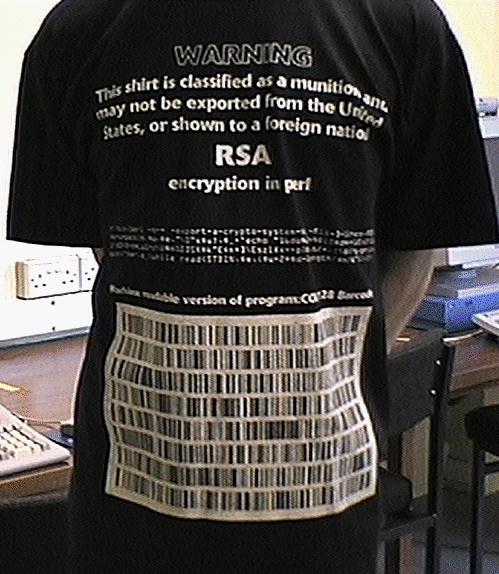
RSA munitions T-shirt

Back when the US government classified strong encryption as “munitions,” RSA public key cryptography was illegal to export. In 1995, Adam Back protested this by creating a terse, obfuscated implementation of RSA in Perl code and used it as an email signature.

The code was also printed on T-shirts. The shirt was classified as munitions because it contained source code for strong encryption. More on the shirt here.

Adam Back's munitions T-shirt

This was the code:

#!/bin/perl -s-- -export-a-crypto-system-sig -RSA-3-lines-PERL
$m=unpack(H.$w,$m."\0"x$w),$_=`echo "16do$w 2+4Oi0$d*-^1[d2%Sa
2/d0<X+d*La1=z\U$n%0]SX$k"[$m*]\EszlXx++p|dc`,s/^.|\W//g,print
pack('H*',$_)while read(STDIN,$m,($w=2*$d-1+length$n&~1)/2)

My initial intention was to unpack the code, explaining each piece in detail. I don’t have the time or patience for that, and I imagine many readers don’t either. For more of a blow-by-blow explanation, see this commentary from 1995.

dc

In the middle of the code is

    echo ... | dc

This is the most dense and most important part of the code. Perl calls the dc calculator to do the arbitrary precision arithmetic that RSA encryption requires.

I’ve written about bc several times. bc (“basic calculator”) was a originally a more user-friendly wrapper around the reverse-Polish dc (“desktop calculator”). dc is still part of every Unix and Unix-like system, but I imagine bc is far more popular.

The important feature of dc for this post is that it is stack-based, meaning that users would push data and commands on to the stack and pop results off the stack. A sequence of commands that might be understandable when interactively using dc would look cryptic in a transcript. This is part of what makes the code so cryptic.

I’ll parse just a tiny bit of the dc code to give a flavor of what it does. The first four characters 16do instructs dc to push 16 on to the stack, duplicate it, and set the output radix to 16, i.e. these four characters tell dc to work in hexadecimal.

Believe it or not, the dc code is computing

mk mod n

using fast exponentiation, which is the key step in the RSA algorithm.

Textbook RSA

Note that Adam Back’s code is computing what we would now call textbook RSA, not RSA as it has been refined over the years and is currently implemented.

Related posts

Hacking the lehmer64 RNG

A couple days ago I wrote about hacking the Mersenne Twister. I explained how to recover the random number generator’s internal state from a stream of 640 outputs.

This post will do something similar with the lehmer64 random number generator. This generator is very simple to implement. Daniel Lemire found it to be “the fastest conventional random number generator that can pass Big Crush,” a well-respected test for pseudorandom number generators.

Implementing lehmer64

The lehmer64 generator can be implemented in C by

__uint128_t g_lehmer64_state;

uint64_t lehmer64() {
    g_lehmer64_state *= 0xda942042e4dd58b5ULL;  
  return g_lehmer64_state >> 64;
}

The analogous code in Python would have to simulate the overflow behavior of a 128-bit integer by reducing the state mod 2128 after the multiplication.

Reverse engineering lehmer64 is easier than reverse engineering the Mersenne Twister because only three outputs are needed. However, the theory behind the exploit is more sophisticated. See [1].

The following code sets the state to an arbitrary initial seed value and generates three values.

#include <stdio.h>
#include <stdint.h>

int main(void)
{
    g_lehmer64_state = 0x4789499d78770934; // seed
    for (int i = 0; i < 3; i++) {
        printf("0x%016lx\n", lehmer64());
    }

    return 0;
}

The code prints the following.

0x3d144d12822bcc2e
0x85a67226191a568d
0x53e803dffc88e8f8

Exploiting lehmer64

Here is Python code for recovering the state of the lehmer64 generator given in [1].

def reconstruct(X):
    a = 0xda942042e4dd58b5
    r = round(2.64929081169728e-7 * X[0] + 3.51729342107376e-7 * X[1] + 3.89110109147656e-8 * X[2])
    s = round(3.12752538137199e-7 * X[0] - 1.00664345453760e-7 * X[1] - 2.16685184476959e-7 * X[2])
    t = round(3.54263598631140e-8 * X[0] - 2.05535734808162e-7 * X[1] + 2.73269247090513e-7 * X[2])
    u = r * 1556524 + s * 2249380 + t * 1561981
    v = r * 8429177212358078682 + s * 4111469003616164778 + t * 3562247178301810180
    state = (a*u + v) % (2**128)
    return state

Let’s call reconstruct with the output of our C code.

X = [0x3d144d12822bcc2e, 0x85a67226191a568d, 0x53e803dffc88e8f8]
print( hex( reconstruct(X) ) )

This prints

0x3d144d12822bcc2e1b81101c593761c4

Now for the confusing part: at what point is the number above the state of the generator? Is it the state before or after generating the three values? Neither! It is the state after generating the first value.

We can verify this by modifying the C code as follows and rerunning it.

void print_u128(__uint128_t n)
{
    printf("0x%016lx%016lx\n",
           (uint64_t)(n >> 64),      // upper 64 bits
           (uint64_t)n);             // lower 64 bits
}

int main(void)
{
    g_lehmer64_state = 0x4789499d78770934; // seed
    for (int i = 0; i < 3; i++) {
        printf("0x%016lx\n", lehmer64());
        printf("state: ");
        print_u128(g_lehmer64_state);
    }
 
    return 0;
}

The main goal of [1] is to recover the state of the PCG generator, not the lehmer64 generator. The latter was a side quest. Recovering the state of PCG64 is much harder; the authors estimate it takes about 20,000 CPU-hours. The paper shows that a technique used as part of pursuing their main goal can quickly recover the lehmer64 state.

Related posts

[1] Charles Bouillaguet, Florette Martinez, and Julia Sauvage. Practical seed-recovery for the PCG Pseudo-Random Number Generator. IACR Transactions on Symmetric Cryptology. ISSN 2519-173X, Vol. 2020, No. 3, pp. 175–196.

Quantum Y2K

I’m skeptical that quantum computing will become practical. However, if it does become practical before we’re prepared, the world’s financial system could collapse. Everyone agrees we should prepare for quantum computing, even those of us who doubt it will be practical any time soon.

Quantum computers exist now, but the question is when and if a cryptographically relevant quantum computer (CRQC) is coming. At the moment, a quantum computer cannot factor 21 without cheating (i.e. not implementing circuits that you know a priori won’t be needed). But that could change suddenly. And some believe quantum computers could quickly go from being able to factor numbers with two digits to being able to factor numbers with thousands of digits (i.e. breaking RSA encryption) without much incremental transition between.

The move to post-quantum encryption may be a lot like Y2K, fixing vast amounts of 20th century software that represented years with two digits. Y2K turned out to be a big nothingburger, but only because the world spent half a trillion dollars on preparation to make sure it would be a big nothingburger.

Programmers in the 1970s obviously knew that the year 2000 was coming, but they also knew that they needed to conserve bytes at the time. And they assumed, reasonably but incorrectly, that their software would all be replaced before two-digit dates became a problem.

Programmers still need to conserve bytes, though this is less obvious today. Quantum-resistant signatures and encryption keys are one or two orders of magnitude bigger. This takes up bandwidth and storage space, which may or may not be a significant problem, depending on context. Programmers may conclude that it’s not (yet) worth the extra overhead to use post-quantum encryption. Like their counterparts 50 years ago, they may assume, rightly or wrongly, that their software will be replaced by the time it needs to be.

Moving to post-quantum cryptography ASAP is not a great idea if you can afford to be more strategic. It takes many years to gain confidence that new encryption algorithms are secure. The SIKE algorithm, for example, was a semi-finalist the NIST post-quantum encryption competition, but someone found a way to break it using an hour of computing on a laptop.

Another reason to not be in a hurry is that it may be possible to be more clever than simply replacing pre-quantum algorithms with post-quantum analogs. For example, some blockchains are exploring zero-knowledge proofs as a way to aggregate signatures. Simply moving to post-quantum signatures could make every transaction block 100 times bigger. But replacing a set of signatures by a (post-quantum) zero-knowledge proof of the existence of the signatures, transaction blocks could be smaller than now.

As with Y2K, the move to post-quantum cryptography will be gradual. Some things have already moved, and some are in transition now. You may have seen the following warning when connecting to a remote server.

** WARNING: connection is not using a post-quantum key exchange algorithm.
** This session may be vulnerable to "store now, decrypt later" attacks.
** The server may need to be upgraded. See https://openssh.com/pq.html

Key sizes don’t matter as much to sftp connections as they do to blockchains. And the maturity of post-quantum algorithms is mitigated by OpenSSH using hybrid encryption: well-established encryption (like ECDH) wrapped by newer quantum-resistant encryption (like MK-KEM). If the newer algorithm isn’t as secure as expected, you’re no worse off than if you had only used the older algorithm.

When clocks rolled over from 1999 to 2000 without incident, many people felt the concern about Y2K had been overblown. Maybe something similar will happen with quantum computing. Let’s hope so.

Related posts

Proving you know a product

There is a way to prove that you know two numbers a and b, and their product c = ab, without revealing a, b, or c. This isn’t very exciting without more context — maybe you know that 7 × 3 = 21 — but it’s a building block of more interesting zero knowledge proofs, such as proving that a cryptocurrency transaction is valid without revealing the amount of the transaction.

The proof mechanism requires an elliptic curve G and a pairing of G with itself. (More on pairings shortly.) It also requires a generator g of the group structure on G.

The prover takes the three secret numbers and multiplies the generator g by each, encrypting the numbers as ag, bg, and cg. When G is a large elliptic curve, say one with on the order of 2256 points, then computing products like ag can be done quickly, but recovering a from g and ag is impractical. In a nutshell, multiplication is easy but division [1] is practically impossible [2].

The verifier receives ag, bg, and cg. How can he verify that ab = c without knowing a, b, or c? Here’s where pairing come in.

I go more into pairings here, but essentially a pairing is a mapping from two groups to a third group

e: G1 × G2 → GT

such that

e(aP, bQ) = e(P, Q)ab.

In our case G1 and G2 are both equal to the group G above, and the target group GT doesn’t matter for our discussion here. Also, P and Q will both be our generator g.

By the defining property of a pairing,

e(ag, bg) = e(g, g)ab

and

e(cg, g) = e(g, g)c.

So if ab = c, then e(g, g)ab and e(g, g)c will be equal.

Related posts

[1] The literature will usually speak of discrete logarithms rather than division. The group structure on an elliptic curve is Abelian, and so it is usually written as addition. If you write the group operation as multiplication, then you’re taking logs rather than dividing. The multiplicative notation highlights the similarity to working in the multiplicative group modulo a large prime.

[2] The computation is theoretically possible but not possible in practice without spending enormous resources, or inventing a large scale quantum computer. This is the discrete logarithm assumption.