Uncategorized

Learning from historical mistakes

The following extraordinary paragraph comes from Knuth’s TAOCP Volume 4A, right before the last set of exercises.

Many of the exercises below ask a modern reader to find and/or to correct errors in the literature of bygone days. The point is not to gloat over how smart we are in the 21st century; the point is rather to understand that even the pioneers of a subject can stumble. One good way to learn that a set of ideas is not really as simple as it might seem to today’s computer scientists and mathematicians is to observe that some of the world’s leading thinkers had to struggle with the concepts when they were new.

Enumerating trees and circles

A few days ago I wrote a post on counting rooted trees. That post looked at the sequence c(n) which counts the number of rooted trees with n nodes. Here one node is distinguished as the root, but the nodes below the root are not distinguished from each other; all that matters is how the nodes are connected.

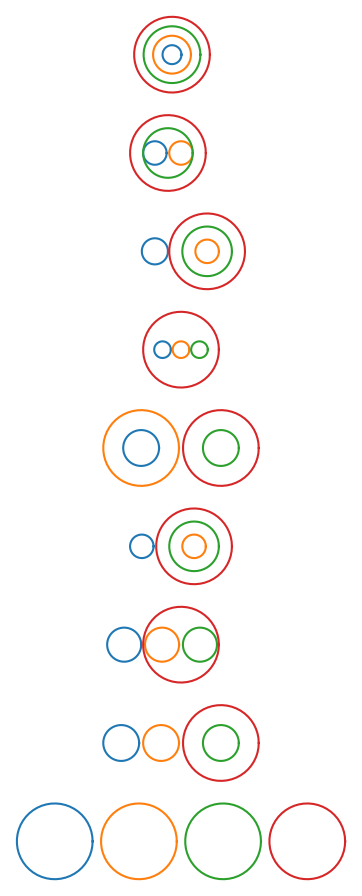
The number of rooted trees with n nodes is the same as the number of ways to configure n − 1 non-overlapping circles. Not only are the counts the same, there is a natural correspondence between the trees and the circles. It’s not obvious that there should be such a correspondence, with the right notation the correspondence is sort of a pun.

The standard way to represent unlabeled trees is as a multiset of their children. We use a multiset, not a set, because some elements will be repeated. We represent a leaf as a pair of parentheses: ().

There is only one rooted tree with one node: ().

There is only one rooted tree with one two nodes: (()). Here the outer parentheses represent the root node and the inner parentheses represent its child.

There are two rooted trees with three nodes, and we can represent them as ((())) and ((),()). The first is the straight line tree: a node that has a single child node that has a single child node. The second is a node that branches to two nodes. (Here’s where we need multisets.)

The four rooted trees with four nodes can be represented as (((()))), ((((),())), ((),(())), and ((),(),(),()).

Here are the nine rooted trees with five nodes:

((((()))))
((((),())))
(((),(())))
(((),(),()))
((()),(()))
((),((())))
((),((),()))
((),(),(()))
((),(),(),())

The correspondence with non-overlapping circles removes the outer parentheses then joins the rest to form circles, with nested parentheses corresponding to concentric circles. A more geometric way to see the correspondence is to start at the bottom of the tree, replace leaves with circles, then work your way up circling connected components.

Permutation roots

Let σ be a permutation on n elements. If there is a permutation τ such that applying τ twice has the same effect on the list of elements as applying σ once, we say σ = τ² and τ is a square root of σ.

If we let our n elements be the integers 0 through n − 1, then we can represent permutations by what they do to this list of numbers. In Python as a tuple of length n and compose permutations with the following function:

import itertools

def compose(sigma, tau):
    "Return the composition σ ∘ τ (apply τ first, then σ)."
    return tuple(sigma[j] for j in tau)

We can always construct permutations that have square roots by squaring a permutation. If we run the following code

tau = (3, 1, 4, 5, 2, 0)
sigma = compose(tau, tau)

we find σ = (5, 1, 2, 0, 4, 3), and by construction (3, 1, 4, 5, 2, 0) is a square root of &sigma, though it’s not the only one.

The following code shows that σ has four roots.

import itertools

def numroots(sigma):
    n = len(sigma)
    c = 0
    for tau in itertools.permutations(range(n)):
        if sigma == compose(tau, tau):
            c += 1
    return c

print( numroots(sigma) )
print( numroots( (1, 2, 3, 4, 5, 0) ) )

It also shows that the rotation (1, 2, 3, 4, 5. 0) has no roots.

The function numroots has runtime proportional to n! and so it’s not practical for large permutations. There is a theorem that says a permutation σ has a square root if and only if the number of cycles it has of every even length is even. See [1].

We can also define cubes and cube roots of permutations, and higher powers and roots.

How common is it for permutations to have square roots, or cube roots, etc.? If you pick a random permutation on n elements, what is the probability that it has a kth root?

This is a hard question in general, but it is equivalent to finding the coefficient of xk in the infinite product

\prod_{m=1}^\infty \exp_{\text{gcd}(m, k)} \left(\frac{x^m}{m}\right)

This is theorem 4.8.3 in [1]. This theorem was the motivation for writing about expq in the previous post.

Although the product is infinite, there’s no need to compute terms in the product that only contribute powers of x higher than you’re interested in. The following Mathematica code will compute the probability that a permutation on n elements has a kth root.

expq[x_, q_] := MittagLefflerE[q, x^q]	 
p[n_, k_] :=  SeriesCoefficient[	 
    Product[expq[x^m/m, GCD[m, k]], {m, 1, n}], {x, 0, n}]

So, for example, the probability that a permutation of 10 elements has a square root is 29/96.

[1] Herbert Wilf. Generatingfunctionology. Available online here.

Solving a chess puzzle with Grok 4.5

I’ve written several posts about using Claude or ChatGPT to generate Prolog or Lean code to solve a chess puzzle. I didn’t think Grok would be up to the task, though I didn’t try it. I’ve heard good things about Grok 4.5, so I gave it a shot. It did great.

Here’s the problem, a variation on the n-queens problem formulated by Martin Gardner.

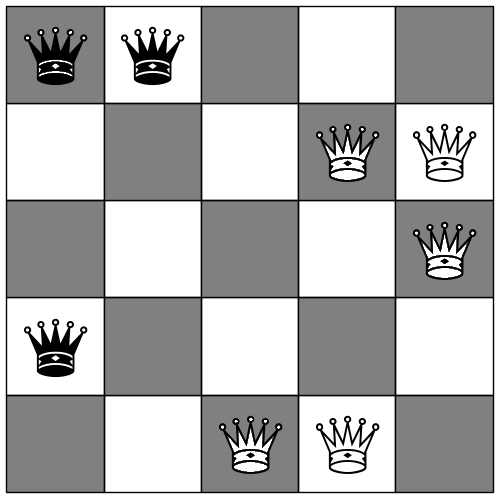
Can you place five white queens and three black queens on a 5 × 5 board so that no queen of one color attacks a queen of another color?

Here’s the prompt I have Grok 4.5.

Generate SWI Prolog code to solve the following chess puzzle. On a 5 by 5 chessboard, place 5 white queens and 3 black queens so that no queen is attacking a queen of the other color. Have the code enumerate all solutions.

The code ran correctly, giving all eight solutions.

I then asked Grok

Now generate Lean 4 code to solve the same puzzle.

The code did not run on the first or second attempts but ran correctly on the third iteration. That’s better than I’ve seen before. It’s not an apples-to-apples comparison, but it has usually taken many iterations with Claude before Lean code would run.

Solutions

There are eight solutions, each being a flip or a rotation of one fundamental solution. Here’s a representative.

SWI Prolog code

:- use_module(library(clpfd)).

%% Enumerate all ways to place 5 white queens and 3 black queens
%% on a 5x5 board so that no queen attacks a queen of the opposite colour.
%% Same-colour queens are allowed to attack each other.
%%
%% Positions are numbered 1..25 in row-major order:
%%   1  2  3  4  5
%%   6  7  8  9 10
%%  11 12 13 14 15
%%  16 17 18 19 20
%%  21 22 23 24 25

solve :-
    solution(Whites, Blacks),
    print_solution(Whites, Blacks),
    fail.
solve :-
    writeln('No more solutions.').

solution(Whites, Blacks) :-
    length(Whites, 5),
    length(Blacks, 3),
    append(Whites, Blacks, All),
    All ins 1..25,
    all_distinct(All),
    % canonical order so each set of positions is generated once
    Whites = [W1,W2,W3,W4,W5],
    W1 #< W2, W2 #< W3, W3 #< W4, W4 #< W5,
    Blacks = [B1,B2,B3],
    B1 #< B2, B2 #< B3, % every black is safe from every white maplist(safe_from_all(Whites), Blacks), label(All). safe_from_all(Whites, Black) :- maplist(no_attack(Black), Whites). %% Two queens do *not* attack each other. no_attack(P, Q) :- R1 #= (P-1) div 5 + 1, C1 #= (P-1) mod 5 + 1, R2 #= (Q-1) div 5 + 1, C2 #= (Q-1) mod 5 + 1, R1 #\= R2, % different row C1 #\= C2, % different column abs(R1-R2) #\= abs(C1-C2). % different diagonal print_solution(Whites, Blacks) :- format('Whites: ~w~n', [Whites]), format('Blacks: ~w~n', [Blacks]), forall(between(1, 5, R), ( forall(between(1, 5, C), ( Pos is (R-1)*5 + C, ( memberchk(Pos, Whites) -> write('W ')
                      ; memberchk(Pos, Blacks) -> write('B ')
                      ; write('. ')
                      )
                    )),
             nl )),
    nl.

Lean 4 code

-- Lean 4 solution for the 5×5 black-and-white queens puzzle.
-- 5 white queens + 3 black queens; no opposite-colour attacks.

def absDiff (a b : Nat) : Nat :=
  if a ≥ b then a - b else b - a

def attacks (p q : Nat × Nat) : Bool :=
  p.1 == q.1 || p.2 == q.2 || absDiff p.1 q.1 == absDiff p.2 q.2

/-- All 25 squares (0-based, row-major). -/
def allPositions : List (Nat × Nat) :=
  (List.range 5).flatMap fun r =>
    (List.range 5).map fun c => (r, c)

/-- Combinations of length exactly `k` (order-preserving). -/
def combinations {α : Type} : Nat → List α → List (List α)
  | 0,     _      => [[]]
  | _,     []     => []
  | k + 1, x::ys  =>
      (combinations k ys).map (fun zs => x :: zs) ++
      combinations (k + 1) ys

def isAttackedBy (pos : Nat × Nat) (queens : List (Nat × Nat)) : Bool :=
  queens.any (fun q => attacks q pos)

/-- Every solution as a pair (white squares, black squares). -/
def solve : List (List (Nat × Nat) × List (Nat × Nat)) :=
  (combinations 3 allPositions).foldl (fun acc blacks =>
    let forbidden := allPositions.filter fun p =>
      blacks.contains p || isAttackedBy p blacks
    let available := allPositions.filter fun p =>
      !(forbidden.contains p)
    acc ++ (combinations 5 available).map fun whites => (whites, blacks)
  ) []

/-- Pretty-print one board. -/
def printBoard (whites blacks : List (Nat × Nat)) : IO Unit := do
  for r in List.range 5 do
    let mut row := ""
    for c in List.range 5 do
      let p := (r, c)
      row := row ++
        (if whites.contains p then "W "
         else if blacks.contains p then "B "
         else ". ")
    IO.println row
  IO.println ""

/-- Enumerate and display every solution. -/
def main : IO Unit := do
  let sols := solve
  IO.println s!"Found {sols.length} solutions.\n"
  for p in (List.range sols.length).zip sols do
    let i := p.1
    let (whites, blacks) := p.2
    IO.println s!"Solution {i + 1}:"
    printBoard whites blacks

#eval main

Visualizing Medical Code Hierarchy

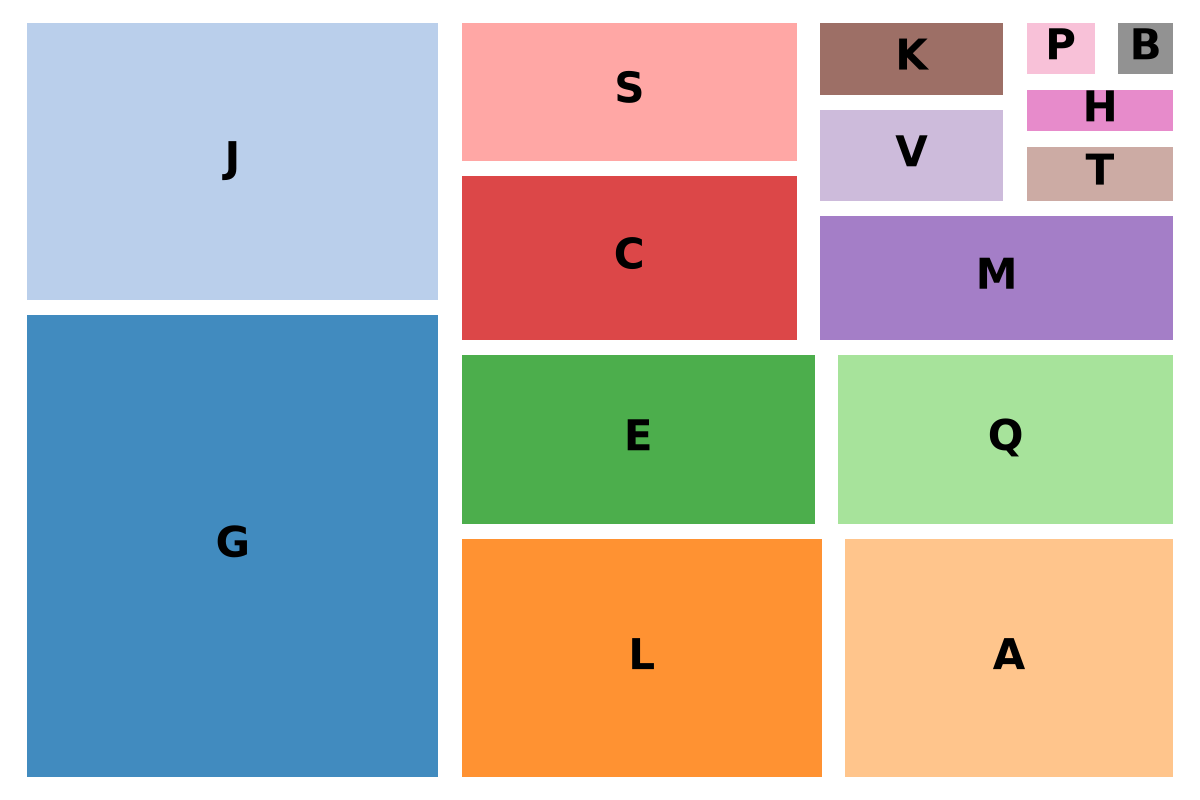
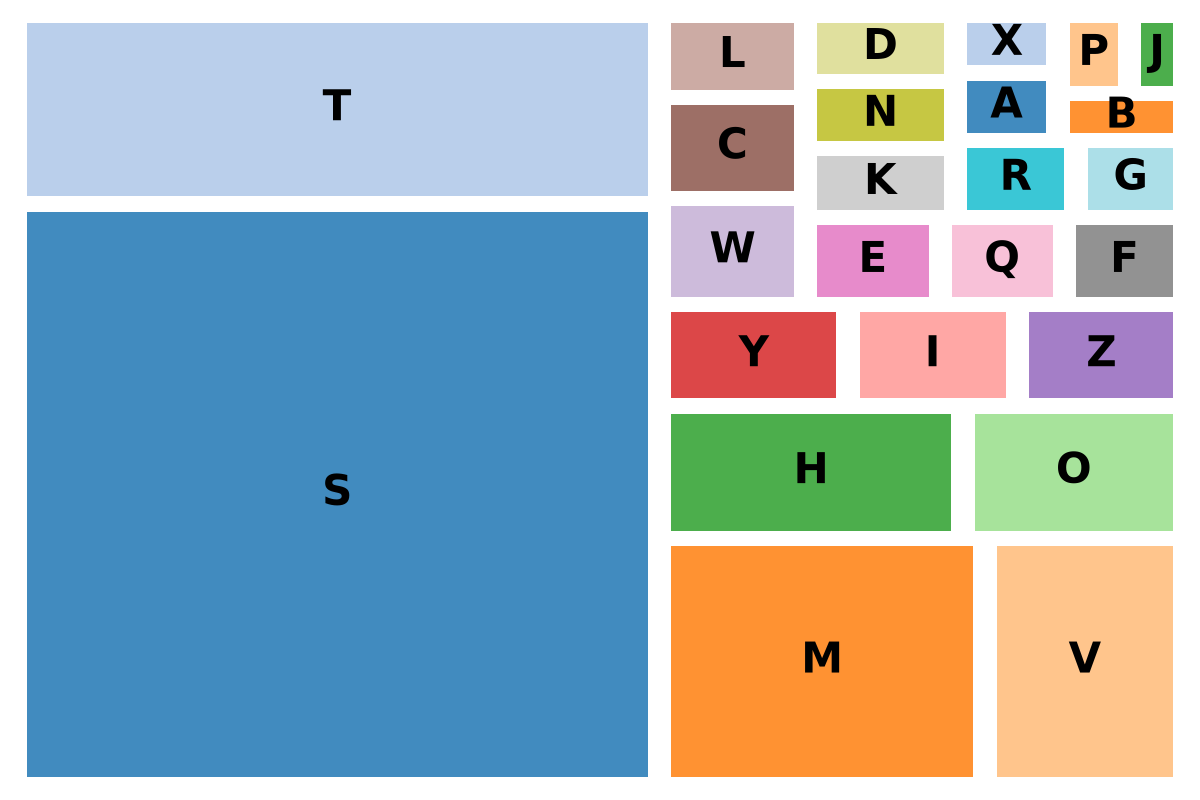
Quick follow up to the previous two posts on ICD-10 codes and HCPCS codes. This post uses Python’s squarify library to create treemaps visualizing how many codes begin with each letter.

Here’s the treemap for HCPCS codes.

HCPCS code treemap

And here’s the treemap for ICD-10 codes.

HCPCS code treemap

The sizes of the squares are proportional to the number of codes beginning with that letter. Note that they are not necessarily proportional to how often codes are used.

The HCPCS map omits R and U because these are tiny relative to the rest. The ICD-10 map omits U for the same reason.

Here’s the code that was used to create the HCPCS map.

import matplotlib.pyplot as plt
import squarify

# HCPCS
data = {
    "G": 2010,
    "J": 1232,
    "L": 940,
    "A": 862,
    "E": 671,
    "Q": 639,
    "C": 619,
    "S": 533,
    "M": 506,
    "V": 212,
    "K": 175,
    "T": 114,
    "H": 94,
    "P": 59,
    "B": 51,
  # "U": 5,
  # "R": 3,
}

labels = list(data.keys())
sizes = list(data.values())

# Labels are just the letters (no counts)
display_labels = labels

# Color map — one distinct color per box
colors = plt.cm.tab20.colors[: len(labels)]

fig, ax = plt.subplots(figsize=(12, 8))
squarify.plot(
    sizes=sizes,
    label=display_labels,
    color=colors,
    alpha=0.85,
    ax=ax,
    text_kwargs={"fontsize": 30, "weight": "bold"},
    pad=True,
)
ax.axis("off")

plt.tight_layout()
plt.savefig("treemap.png", dpi=72)
plt.show()

The code to create the ICD-10 map differs only in its data.

# ICD-10
data = {
    "S": 31052, 
    "T": 10090, 
    "M":  6665, 
    "V":  4086, 
    "H":  3330, 
    "O":  2437, 
    "Y":  1590, 
    "I":  1427, 
    "Z":  1411, 
    "W":  1290, 
    "C":  1226, 
    "L":  1000, 
    "E":   971, 
    "Q":   894, 
    "F":   871, 
    "K":   857, 
    "N":   836, 
    "D":   824, 
    "R":   773, 
    "G":   700, 
    "A":   573, 
    "X":   495, 
    "B":   495, 
    "P":   463, 
    "J":   360, 
  # "U":     3,
}  

ICD-10 chapters and code letters

I’ve been thinking about ICD-10 codes; they come up a lot in my work.

The ICD-10-CM standard is divided into 21 chapters, which generally correspond to the first letter of a code. However, a chapter may contain blocks beginning with more than one letter, and codes starting with a single letter, namely D, can span two chapters.

Here’s a diagram I made to visualize the relationship between chapters and initial letters of codes.

Notice there’s no letter U on the diagram. That’s because U is reserved for special/provisional codes.

Related posts

Writing Prolog with ChatGPT

A few days ago I wrote about using Claude to solve a chess puzzle by writing Prolog code. This morning I tried a similar chess puzzle with ChatGPT. The task is to place a queen, king, rook, bishop, and knight on a 4 by 4 chessboard so no piece attacks another.
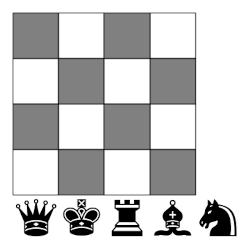
Of course there’s not a lot of market demand for solving chess puzzles, but there is demand for solving real-world problems that amount to logic puzzles. Experiments with chess puzzles suggest writing Prolog with LLM help might be pleasant. The syntax of Prolog can be a little odd, but the LLM handles that. And because Prolog has been around so long without changing much, you’d expect LLMs to be good at generating code in it. [1]

I gave ChatGPT this prompt:

Write a SWI Prolog program to solve the following chess puzzle. Place a queen, king, rook, bishop, and knight on a 4 by 4 chessboard so no piece attacks another. Print all solutions.

It produced a file chess4.pl (below) that I ran with

swipl -q -s chess4.pl -g solve -t halt

It found all 16 solutions:

Solution 1:
  queen=1-2  king=2-4  rook=3-1  bishop=4-3  knight=4-4
. K . N
. . . B
Q . . .
. . R .

Solution 2:
  queen=1-2  king=4-3  rook=2-4  bishop=3-1  knight=4-1
. R . .
. . . K
Q . . .
. . B N

...

Here’s the code.

% chess4.pl
% Place queen, king, rook, bishop, and knight on a 4x4 board
% so that no piece attacks another.

:- use_module(library(lists)).

square(X-Y) :-
    between(1, 4, X),
    between(1, 4, Y).

solve :-
    findall(Board, solution(Board), Boards),
    print_solutions(Boards, 1),
    length(Boards, Count),
    format('Total solutions: ~d~n', [Count]).

solution(Board) :-
    Pieces = [queen, king, rook, bishop, knight],
    findall(S, square(S), Squares),
    place_pieces(Pieces, Squares, Board),
    safe(Board).

place_pieces([], _, []).
place_pieces([Piece | Pieces], Squares, [Piece-Square | Board]) :-
    select(Square, Squares, RemainingSquares),
    place_pieces(Pieces, RemainingSquares, Board).

safe(Board) :-
    safe(Board, Board).

safe([], _).
safe([Piece-Square | Rest], Board) :-
    forall(
        member(OtherPiece-OtherSquare, Rest),
        non_attacking(Piece-Square, OtherPiece-OtherSquare, Board)
    ),
    safe(Rest, Board).

non_attacking(P1-S1, P2-S2, Board) :-
    \+ attacks(P1, S1, S2, Board),
    \+ attacks(P2, S2, S1, Board).

% Attack rules

attacks(king, X1-Y1, X2-Y2, _) :-
    X1-Y1 \= X2-Y2,
    DX is abs(X1 - X2),
    DY is abs(Y1 - Y2),
    DX =< 1,
    DY =< 1. attacks(knight, X1-Y1, X2-Y2, _) :- DX is abs(X1 - X2), DY is abs(Y1 - Y2), ( DX =:= 1, DY =:= 2 ; DX =:= 2, DY =:= 1 ). attacks(rook, S1, S2, Board) :- same_rank_or_file(S1, S2), clear_line(S1, S2, Board). attacks(bishop, S1, S2, Board) :- same_diagonal(S1, S2), clear_line(S1, S2, Board). attacks(queen, S1, S2, Board) :- ( same_rank_or_file(S1, S2) ; same_diagonal(S1, S2) ), clear_line(S1, S2, Board). same_rank_or_file(X1-Y1, X2-Y2) :- ( X1 =:= X2 ; Y1 =:= Y2 ). same_diagonal(X1-Y1, X2-Y2) :- DX is abs(X1 - X2), DY is abs(Y1 - Y2), DX =:= DY. % For sliding pieces, make sure no piece blocks the path. clear_line(X1-Y1, X2-Y2, Board) :- step(X1, X2, SX), step(Y1, Y2, SY), NX is X1 + SX, NY is Y1 + SY, clear_path(NX-NY, X2-Y2, SX-SY, Board). clear_path(Target, Target, _, _) :- !. clear_path(X-Y, Target, SX-SY, Board) :- \+ occupied(X-Y, Board), NX is X + SX, NY is Y + SY, clear_path(NX-NY, Target, SX-SY, Board). step(A, B, 0) :- A =:= B. step(A, B, 1) :- B > A.
step(A, B, -1) :-
    B < A.

occupied(Square, Board) :-
    member(_-Square, Board).

% Printing

print_solutions([], _).
print_solutions([Board | Rest], N) :-
    format('Solution ~d:~n', [N]),
    print_coordinates(Board),
    print_board(Board),
    nl,
    N1 is N + 1,
    print_solutions(Rest, N1).

print_coordinates(Board) :-
    member(queen-Q, Board),
    member(king-K, Board),
    member(rook-R, Board),
    member(bishop-B, Board),
    member(knight-N, Board),
    format('  queen=~w  king=~w  rook=~w  bishop=~w  knight=~w~n',
           [Q, K, R, B, N]).

print_board(Board) :-
    forall(
        between(1, 4, Row0),
        (
            Y is 5 - Row0,
            forall(
                between(1, 4, X),
                (
                    piece_at(X-Y, Board, Symbol),
                    format('~w ', [Symbol])
                )
            ),
            nl
        )
    ).

piece_at(Square, Board, Symbol) :-
    member(Piece-Square, Board),
    !,
    piece_symbol(Piece, Symbol).
piece_at(_, _, '.').

piece_symbol(queen,  'Q').
piece_symbol(king,   'K').
piece_symbol(rook,   'R').
piece_symbol(bishop, 'B').
piece_symbol(knight, 'N').

[1] I’ve played around with generating Prolog and Lean this weekend, and I’ve had better results with Prolog. The problems with Lean haven’t been Lean per se but the Mathlib library. The library is frequently refactored, which makes sense for a young language, but this makes it harder to generate and debug code.

Subscribe by email

Readers have subscribed to this blog via email almost from its beginning in 2008, but how they have subscribed has changed several times. I’ve used several services to provide email subscription that have come and gone.

For the past two years I’ve been using Substack to send out emails announcing new blog posts. That has worked out well. Substack delivers email reliably, and that’s all I wanted. I’m not active on Substack other than using it to an email. I give a brief introduction to the latest two or three blog posts in each email, and sometimes I include additional ideas that occurred to me later.

If you’d like to get blog post announcements and a little extra commentary via email, sign up for my free Substack newsletter here.

If you’d like to learn about new posts sooner, you can subscribe via RSS or follow me on X or Mastodon.

Another Gaussian approximation

The function

(1 + cos(x))/2

gives a fair approximation to the Gaussian density

exp(−x²)

You can make the approximation much better by raising it to a power. The function

((1 + cos(x))/2)4

gives a good lower bound and

((1 + cos(x))/2)3.5597

gives a good upper bound. More on that here.

There are other ways of improving the cosine approximation to the Gaussian. Yesterday I came across one I hadn’t seen before, adding a sin(x) term to x.

(1 + cos(sin(x) + x))/2

This function matches the first few terms of the power series for exp(−x²) and has an error on the order of x6/240. You can’t see the difference between the two functions in a plot for −4 ≤ x ≤ 4.

***

There’s a tension between the previous two statements. If the error in on the order of x6/240 then we’d expect the error to be huge at x = 4. We have

46/240 = 17.07

and yet

exp(−4²) − ((1 + cos(4 + sin(4)))/2) = −0.002579,

i.e. the error is between 3 and 4 orders of magnitude smaller than we might expect.

We have an alternating series, so the truncation error should be roughly equal to the first term after the truncation, right? No, the alternating series theorem doesn’t apply because the absolute values of the terms in the series are not decreasing yet for x = 4. The terms have to decrease eventually because the series has infinite radius of convergence, but they’re not decreasing at the 6th term; the terms will get much larger in absolute value before they get smaller.

The basic alternating series theorem gives only an upper bound on truncation error, but there are extensions that also give a lower bound. I wrote about these extensions a few weeks ago. But they don’t apply here because the terms have not started decreasing in absolute value.

Update: See further discussion in the post It’s not just Taylor series.

Changing one character in a PDF

I saw a post on X saying

Changing a hyphen to an en-dash increases your PDF file size by ~10 bytes.

My first thought was that it had something to do with hyphen being an ASCII character and an en-dash not. Changing a hyphen to an en-dash would make a UTF-8 encoded text file a couple bytes longer. (See why here.) Maybe adding one non-ASCII character could cause the file to include a glyph it didn’t before.

I did a couple experiments. I made a minimal LaTeX file with only the text

    See pages 9-10.

and another with

    See pages 9--10.

(In LaTeX, a hyphen compiles to a hyphen and two hyphens compile to an en-dash.)

I compiled both files using pdflatex. The PDF with the hyphen was 13172 bytes and the one with the en-dash was 13099 bytes. Replacing the hyphen with the en-dash made the file 73 bytes smaller.

I repeated the experiment with a Libre Office ODT document. Changing the hyphen to an en-dash reduced the file size from 13548 bytes to 13514 bytes.

Then I went back to LaTeX and pasted a paragraph of lorem ipsum text into both files. Now the file with the hyphen produced a 18131 byte PDF and the file with the en-dash produced a 18203 byte PDF. So in this instance changing the hyphen to an en-dash increased the size of the file by 72 bytes.

After adding the lorem ipsum text to the ODT files, the PDF resulting from the file with the hyphen was 23 bytes larger, 17846 bytes versus 17823 bytes.

PDFs are complicated. Changing one character can make the file bigger or smaller, by an unpredictable amount. It depends, among other things, on what software was used to create the PDF. Even changing one letter in an all-ASCII text can change the size of the PDF, I suppose due to some internal text compression and aesthetic control characters. I don’t pretend to understand what’s going on inside a PDF.

Related posts