Solving the RK4 design equations

I was digging into the Runge-Kutta method for solving differential equations and a line from [1] piqued my curiosity.

These calculations, which are not reproduced in Kutta’s paper (they are however in Huen (1900)), are very tedious.

The calculations are a set of eight constraints that the parameters of a fourth-order Runge-Kutta method must satisfy. I wondered how well Mathematica might have done at assisting Mr. Huen in his “very tedious” calculations if it had been available in 1900.

I go into Runge-Kutta methods in this post. Here I’d like to concentrate on a step in the design of the methods, namely solving the set of equations alluded in the quote above.

\begin{align*} b_1 + b_2 + b_3 + b_4 &= 1 \\ b_2 c_2 + b_3 c_3 + b_4 c_4 &= \frac{1}{2} \\ b_2 c_2^2 + b_3 c_3^2 + b_4 c_4^2 &= \frac{1}{3} \\ b_3 a_{32} c_2 + b_4(a_{42} c_2 + a_{43} c_3) &= \frac{1}{6} \\ b_2 c_2^3 + b_3 c_3^3 + b_4 c_4^3 &= \frac{1}{4} \\ b_3 c_3 a_{32} c_2 + b_4 c_4(a_{42} c_2 + a_{43} c_3) &= \frac{1}{8} \\ b_3 a_{32} c_2^2 + b_4(a_{42} c_2^2 + a_{43} c_3^2) &= \frac{1}{12} \\ b_4 a_{43} a_{32} c_2 &= \frac{1}{24} \end{align*}

The first thing to note is that there are 10 variables and only 8 equations, and so the solution is not fully determined. What we think of as the fourth order Runge-Kutta method is in fact a fourth order Runge-Kutta method.

One could argue that we should have b2 = b3 and c2 = c3. With these additional equations, the system of equations has a unique solution, and Mathematic finds it easily.

eqs = {
    b1 + b2 + b3 + b4 == 1,
    b2*c2 + b3*c3 + b4*c4 == 1/2,
    b2*c2^2 + b3*c3^2 + b4*c4^2 == 1/3,
    b3*a32*c2 + b4*(a42*c2 + a43*c3) == 1/6,
    b2*c2^3 + b3*c3^3 + b4*c4^3 == 1/4,
    b3*c3*a32*c2 + b4*c4*(a42*c2 + a43*c3) == 1/8,
    b3*a32*c2^2 + b4*(a42*c2^2 + a43*c3^2) == 1/12,
    b4*a43*a32*c2 == 1/24,
    b2 == b3,
    c2 == c3
};

vars = {b1, b2, b3, b4, c2, c3, c4, a32, a42, a43};

solution = Solve[eqs, vars]

This returns the parameters used for the version of Runge-Kutta presented in every textbook.

If you keep the requirement b2 = b3 but substitute the requirement 2c2 = c3 for c‘s Mathematica will return the coefficients for the so-called Runge-Kutta 3/8 rule. This method has some slight advantages by some criteria.

In 1951 Gill [2] discovered a fourth order Runge-Kutta rule optimized for running in extremely constrained computer hardware. It’s a strange method, with irrational parameters, but one that was a very clever response to the limitations of its time.

Update: See this post for a discussion of the parameters and constriants for higher-ordered RK methods.

Related posts

[1] Hairer, Nørsett, and Wanner. Solving Ordinary Differential Equations I: Nonstiff Problems. Springer-Verlag 1987.

[2] A. Gill. A process for the step-by-step integration of differential equations in an automatic digital computing machine. Proc. Cambridge Philos. Soc., vol 27, pp 95–108.

exp_q

The function expq(x) is defined by taking the power series for exp(x) and keeping only the terms whose index is a multiple of q. For example, exp2(x) keeps only the even-numbered terms in the exponential power series and so equals cosh(x).

\exp_2(x) = 1 + \frac{x^2}{2!} + \frac{x^4}{4!} + \frac{x^6}{6!} + \cdots = \cosh(x)

In general,

\exp_q(x) = \sum_{n=0}^\infty [q \mid n] \frac{x^n}{n!} = \sum_{n=0}^\infty \frac{x^{nq}}{(nq)!}

The first sum uses Iverson’s bracket notation: a Boolean expression in brackets denotes the function that returns 1 when the expression is true and zero when it is false. Here the bracket equals 1 when q divides n and is zero otherwise.

Closed forms

Let ω = exp(2πi / q). Then

\exp_q(x) = \frac{1}{q}\sum_{k=0}^{q-1} \exp(\omega^k x)

This lets us find closed-form expressions for expq(x). For example, when q = 4, ω = i and

\exp_4(x) = \frac{1}{2}\left( \cosh(x) + \cos(x) \right)

Here’s a proof of the identity above:

\begin{align*} \frac{1}{q} \sum_{k=0}^{q-1} \exp(\omega^k x) &= \frac{1}{q} \sum_{k=0}^{q-1} \sum_{n=0}^\infty \frac{\omega^{kn}x^n}{n!} \\ &= \sum_{n=0}^\infty \left( \frac{1}{q} \sum_{k=0}^{q-1} \omega^{kn}\right) \frac{x^n}{n!} \\ &= \sum_{n=0}^\infty [q \mid n] \frac{x^n}{n!} \\ &= \exp_q(x) \end{align*}

In the proof we used the identity

\frac{1}{q} \sum_{k=0}^{q-1} \omega^{kn} = [q \mid n]

which is important in deriving the properties of the discrete Fourier transform.

Differential equations

The first time I saw the function expq(x) was in differential equations, though I didn’t know at the time the function had a name.

When a course in differential equations gets to power series solutions, a common example or homework problem is to solve

y^{(k)}(x) = y(x)

for k = 3 or 4, i.e. to find a function that equals its third or fourth derivative.

If the initial conditions are

y(0) = 0

and

y^\prime(0) = y^{\prime\prime}(0) = \cdots = y^{(k-1)}(0) = 0

the unique solution to

y^{(k)}(x) = y(x)

is y(x) = expk(x).

Mathematica and Mittag-Leffler

Mathematica does not have a built-in function implementing expq(x), but it does have an implementation of the Mittag-Leffler function, and so thanks to a relation between this function and expq(x) you can implement the latter as

expq[x_, q_] := MittagLefflerE[q, x^q]

Combinatorics

The first time I saw the notation expq(x) was in combinatorics. I had intended to include an application from that book here, but I make that the topic for the next post.

Derivative equals inverse

Here’s kind of a strange problem with an interesting solution: find a function f such that the derivative of f equals the inverse of f for all positive x.

f ′(x) = f−1(x)

This is a differential equation, but a very unusual one, one that cannot be solved using any of the techniques taught in a class on differential equations.

The unique solution is

f(x) = φ(x / φ)φ

where φ is the golden ratio. What an unexpected appearance of the golden ratio!

The problem was proposed by H. L. Nelson and solved by A. C. Hindmarsh. See The American Mathematical Monthly, Vol. 76, No. 6 p. 696.

Real and imaginary parts

The previous post announced some notes I wrote up based on an article by Henry Baker implementing functions of a complex variable in terms of functions of a real variable. That is, it finds functions u(x, y) and v(x, y) such that

f(x + iy) = u(x, y) + i v(x, y)

where xyu, and v are all real-valued. Not only that, but if f is an elementary function, so are u and v. Here “elementary” has a technical meaning, but essentially it means functions that you could evaluate on a scientific calculator. A couple of the functions might be unfamiliar, such as sgn and atan2, but there are no functions like the gamma function that are defined in terms of integrals.

One application of Baker’s equations would be to bootstrap a math library that doesn’t support complex numbers into one that does. But the equations could be useful in pure math when you’d like to have a convenient expression for the real or imaginary part of a function.

The real and imaginary parts of a complex analytic function are harmonic functions. So the functions on the right hand side of Baker’s equations satisfy Laplace’s equation:

uxx + uyy = 0

and

vxx + vyy = 0.

Furthermore, the functions u and v form harmonic conjugate pairs, meaning each is the Hilbert transform of the other.

Closed-form solution to the nonlinear pendulum equation

The previous post looks at the nonlinear pendulum equation and what difference it makes to the solutions if you linearize the equation.

If the initial displacement is small enough, you can simply replace sin θ with θ. If the initial displacement is larger, you can improve the accuracy quite a bit by solving the linearized equation and then adjusting the period.

You can also find an exact solution, but not in terms of elementary functions; you have to use Jacobi elliptic functions. These are functions somewhat analogous to trig functions, though it’s not helpful to try to pin down the analogies. For example, the Jacobi function sn is like the sine function in some ways but very different in others, depending on the range of arguments.

We start with the differential equation

θ″(t) + c² sin( θ(t) ) = 0

where c² = g/L, i.e. the gravitational constant divided by pendulum length, and initial conditions θ(0) = θ0 and θ′(0) = 0. We assume −π < θ0 < π.

Then the solution is

θ(t) = 2 arcsin( a cd(ct | m ) )

where a = sin(θ0/2), ma², and cd is one of the 12 Jacobi elliptic functions. Note that cd, like all the Jacobi functions, has an argument and a parameter. In the equation above the argument is ct and the parameter is m.

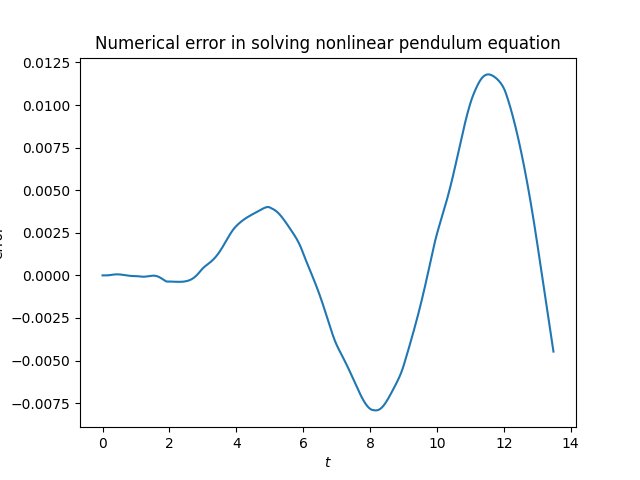
The last plot in the previous post was misleading, showing roughly equal parts genuine difference and error from solving the differential equation numerically. Here’s the code that was used to solve the nonlinear equation.

from scipy.special import ellipj, ellipk
from numpy import sin, cos, pi, linspace, arcsin
from scipy.integrate import solve_ivp

def exact_period(θ):
    return 2*ellipk(sin(θ/2)**2)/pi

def nonlinear_ode(t, z):
    x, y = z
    return [y, -sin(x)]    

theta0 = pi/3
b = 2*pi*exact_period(theta0)
t = linspace(0, 2*b, 2000)

sol = solve_ivp(nonlinear_ode, [0, 2*b], [theta0, 0], t_eval=t)

The solution is contained in sol.y[0].

Let’s compare the numerical solution to the exact solution.

def f(t, c, theta0):
    a = sin(theta0/2)
    m = a**2
    sn, cn, dn, ph = ellipj(c*t, m)
    return 2*arcsin(a*cn/dn)

There are a couple things to note about the code. First,SciPy doesn’t implement the cd function, but it can be computed as cn/dn. Second, the function ellipj returns four functions at once because it takes about as much time to calculate all four as it does to compute one of them.

Here is a plot of the error in solving the differential equation.

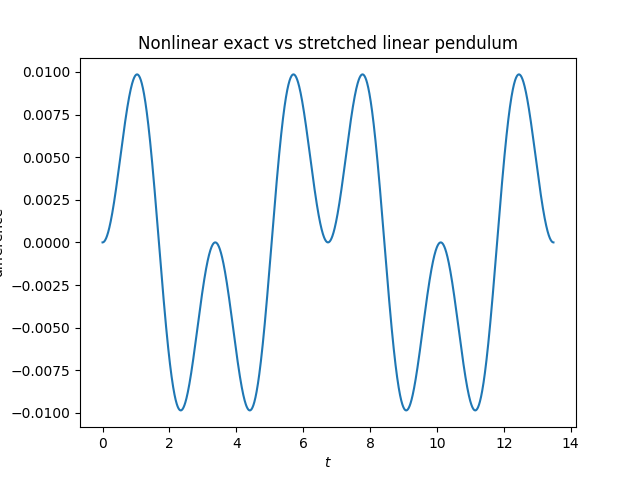
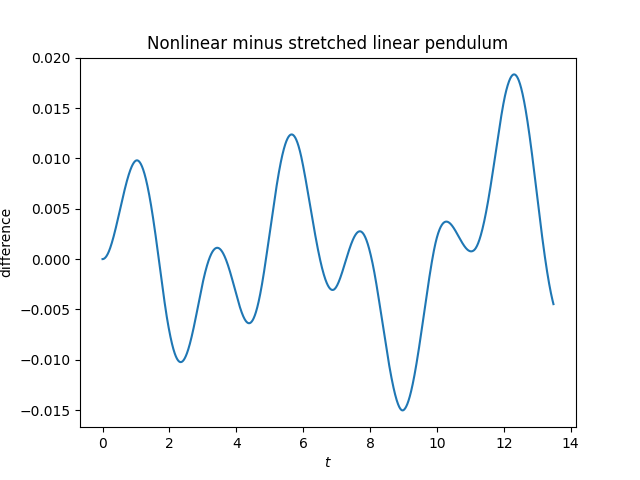
And here is the difference between the exact solution to the nonlinear pendulum equation and the stretched solution to the linear equation.

How nonlinearity affects a pendulum

The equation of motion for a pendulum is the differential equation

\theta'' + \frac{g}{\ell}\sin \theta = 0

where g is the acceleration due to gravity and ℓ is the length of the pendulum. When this is presented in an introductory physics class, the instructor will immediately say something like “we’re only interested in the case where θ is small, so we can rewrite the equation as

\theta'' + \frac{g}{\ell} \theta = 0

Questions

This raises a lot of questions, or at least it should.

  1. Why not leave sin θ alone?
  2. What justifies replacing sin θ with just θ?
  3. How small does θ have to be for this to be OK?
  4. How do the solutions to the exact and approximate equations differ?

First, sine is a nonlinear function, making the differential equation nonlinear. The nonlinear pendulum equation cannot be solved using mathematics that students in an introductory physics class have seen. There is a closed-form solution, but only if you extend “closed-form” to mean more than the elementary functions a student would see in a calculus class.

Second, the approximation is justified because sin θ ≈ θ when θ is small. That’s true, but it’s kinda subtle. Here’s a post unpacking that.

The third question doesn’t have a simple answer, though simple answers are often given. An instructor could make up an answer on the spot and say “less than 10 degrees” or something like that. A more thorough answer requires answering the fourth question.

I address how nonlinear affects the solutions in a post a couple years ago. This post will expand a bit on that post.

Longer period

The primary difference between the nonlinear and linear pendulum equations is that the solutions to the nonlinear equation have longer periods. The solution to the linear equation is a cosine. Solving the equation determines the frequency, amplitude, and phase shift of the cosine, but qualitatively it’s just a cosine. The solution to the corresponding nonlinear equation, with sin θ rather than θ, is not exactly a cosine, but it looks a lot like a cosine, only the period is a little longer [1].

OK, the nonlinear pendulum has a longer period, but how much longer? The period is increased by a factor f0) where θ0 is the initial displacement.

You can find the exact answer in my earlier post. The exact answer depends on a special function called the “complete elliptic integral of the first kind,” but to a good approximation

f(\theta) \approx \frac{1}{\sqrt{\cos(\theta/2)}}

The earlier post compares this approximation to the exact function.

Linear solution with adjusted period

Since the nonlinear pendulum equation is roughly the same as the linear equation with a longer period, you can approximate the solution to the nonlinear equation by solving the linear equation but increasing the period. How good is that approximation?

Let’s do an example with θ0 = 60° = π/3 radians. Then sin θ0 = 0.866 but θ0, in radians, is 1.047, so we definitely can’t say sin θ0 is approximately θ0. To make things simple, let’s set ℓ = g. Also, assume the pendulum starts from rest, i.e. θ'(0) = 0.

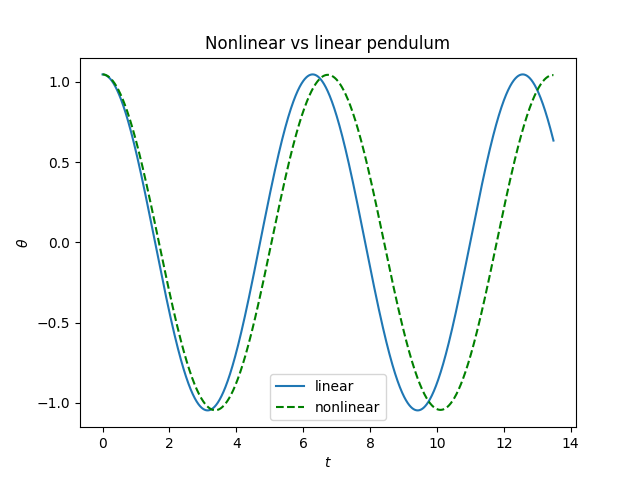
Here’s a plot of the solutions to the nonlinear and linear equations.

Obviously the solution to the nonlinear equation has a longer period. In fact it’s 7.32% longer. (The approximation above would have estimated 7.46%.)

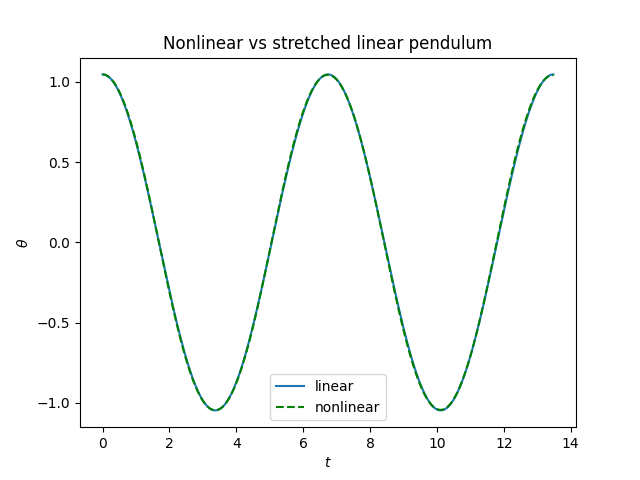
Here’s a plot comparing the solution of the nonlinear equation and the solution to the linear equations with period stretched by 7.32%.

The solutions differ by less than the width of the plotting line, so it’s too small to see. But we can see there’s a difference when we subtract the two solutions.

Here’s a plot of the solutions to the nonlinear and linear equations.

Update: The plot above is misleading. Part of what it shows is numerical error from solving the pendulum equation. When we redo the plot using the exact solution the error is about half as large. And the error is periodic, as we’d expect. See this post for more on the exact solution using Jacobi functions and the differential equation solver that was used to make the original plot.

Related posts

[1] The period of a pendulum depends on its length ℓ, and so we can think of the nonlinear term effectively replacing ℓ by a longer effective length ℓeff.


Differential equation with a small delay

In grad school I specialized in differential equations, but never worked with delay-differential equations, equations specifying that a solution depends not only on its derivatives but also on the state of the function at a previous time. The first time I worked with a delay-differential equation would come a couple decades later when I did some modeling work for a pharmaceutical company.

Large delays can change the qualitative behavior of a differential equation, but it seems plausible that sufficiently small delays should not. This is correct, and we will show just how small “sufficiently small” is in a simple special case. We’ll look at the equation

x′(t) = a x(t) + b x(t − τ)

where the coefficients a and b are non-zero real constants and the delay τ is a positive constant. Then [1] proves that the equation above has the same qualitative behavior as the same equation with the delay removed, i.e. with τ = 0, provided τ is small enough. Here “small enough” means

−1/e exp(−aτ) < e

and

aτ < 1.

There is a further hypothesis for the theorem cited above, a technical condition that holds on a nowhere dense set. The solution to a first order delay-differential like the one we’re looking at here is not determined by an initial condition x(0) = x0 alone. We have to specify the solution over the interval [−τ, 0]. This can be any function of t, subject only to a technical condition that holds on a nowhere-dense set of initial conditions. See [1] for details.

Example

Let’s look at a specific example,

x′(t) = −3 x(t) + 2 x(t − τ)

with the initial condition x(1) = 1. If there were no delay term τ, the solution would be x(t) = exp(1 − t). In this case the solution monotonically decays to zero.

The theorem above says we should expect the same behavior as long as

−1/e < 2τ exp(3τ) < e

which holds as long as τ < 0.404218.

Let’s solve our equation for the case τ = 0.4 using Mathematica.

tau = 0.4
solution = NDSolveValue[
    {x'[t] == -3 x[t] + 2 x[t - tau], x[t /; t <= 1] == t }, 
    x, {t, 0, 10}]
Plot[solution[t], {t, 0, 10}, PlotRange -> All]

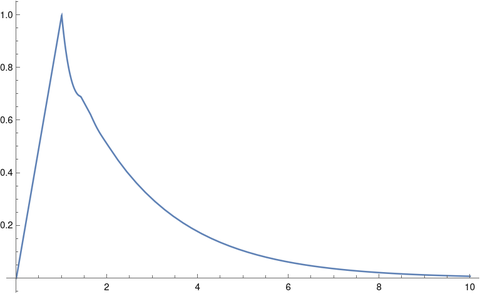
This produces the following plot.

The solution initially ramps up to 1, because that’s what we specified, but it seems that eventually the solution monotonically decays to 0, just as when τ = 0.

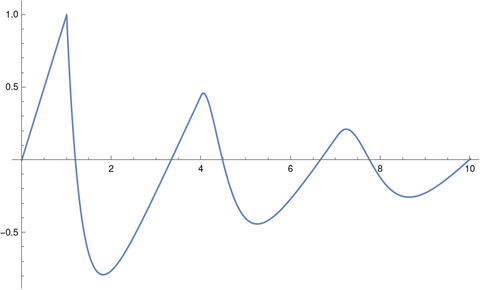
When we change the delay to τ = 3 and rerun the code we get oscillations.

[1] R. D. Driver, D. W. Sasser, M. L. Slater. The Equation x’ (t) = ax (t) + bx (t – τ) with “Small” Delay. The American Mathematical Monthly, Vol. 80, No. 9 (Nov., 1973), pp. 990–995

Bowie integrator and the nonlinear pendulum

I recently learned of Bowie’s numerical method for solving ordinary differential equations of the form

y″ = f(y)

via Alex Scarazzini’s masters thesis [1].

The only reference I’ve been able to find for the method, other than [1], is the NASA Orbital Flight Handbook from 1963. The handbook describes the method as “a method employed by C. Bowie and incorporated in many Martin programs” and says nothing more about its origin.

Martin Company

What does it mean by “Martin programs”? The first line of the foreword of the manual says

This handbook has been produced by the Space Systems Division of the Martin Company under Contract NAS8-S03l with the George C. Marshall Space Flight Center of the National Aeronautics and Space Administration.

The Martin Company was the Glenn L. Martin Company, which became Martin Marietta after merging with American-Marietta Corporation in 1961. The handbook was written after the merger but used the older name. Martin Marietta would go on to become Lockheed Martin in 1995.

Bowie’s method was used “in many Martin programs” and yet is practically unknown in academic circles. Scarazzini’s thesis shows the method works well for his problem.

Nonlinear pendulum

My first thought when I saw the form of differential equations Bowie’s method solves was the nonlinear pendulum equation

y″ = − sin(y)

where the initial displacement y(0) is too large for the approximation sin θ ≈ θ to be sufficiently accurate. I wrote some Python code to try out Bowie’s method on this equation.

import numpy as np

N = 100
y  = np.zeros(N)
yp = np.zeros(N) # y'

y[0] = 1
yp[0] = 0

T = 4*ellipk(np.sin(y[0]/2)**2)
h = T/N

f   = lambda x: -np.sin(x)
fp  = lambda x: -np.cos(x) # f'
fpp = lambda x:  np.sin(x) # f''

for n in range(0, N-1):
    y[n+1] = y[n] + h*yp[n] + 0.5*h**2*f(y[n]) + \
              (h**3/6)*fp(y[n])*yp[n] + \
              (h**4/24)*(fpp(yp[n])*yp[n]**2 + fp(y[n])*f(y[n]))
    yp[n+1] = yp[n] + h*f(y[n]) + 0.5*h**2*fp(y[n])*yp[n] + \
              (h**3/6)*(fpp(yp[n])*yp[n]**2 + fp(y[n])*f(y[n]))

(Update: The code above was updated January 4, 2026 to fix a bug.)

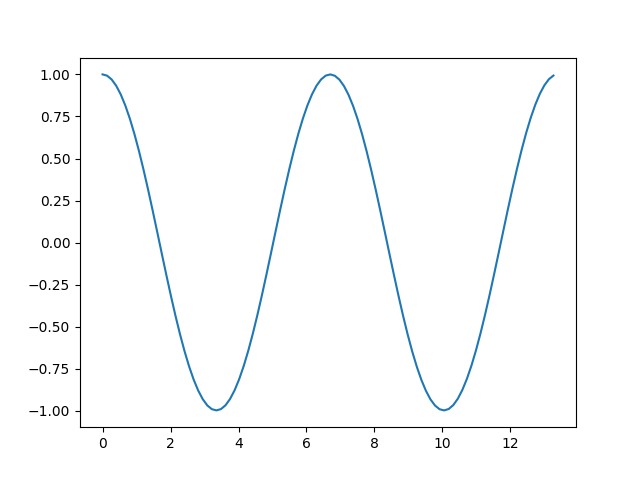
Here’s a graph of the numerical solution.

The solution looks like a cosine, but it isn’t exactly. As I explain here,

The solution to the nonlinear pendulum equation is also periodic, though the solution is a combination of Jacobi functions rather than a combination of trig functions. The difference between the two solutions is small when θ0 is small, but becomes more significant as θ0 increases.

The difference in the periods is more evident than the difference in shape for the two waves. The period of the nonlinear solution is longer than that of the linearized solution.

That’s why the period T in the code is not

2π = 6.28

but rather

4 K(sin² θ0/2) = 6.70.

You’ll also see the period of the nonlinear pendulum given as 4 K(sin θ0/2). As pointed out in the article linked above,

There are two conventions for defining the complete elliptic integral of the first kind. SciPy uses a convention for K that requires us to square the argument.

Related posts

[1] Alex Scarazzini.3D Visualization of a Schwarzschild Black Hole Environment. University of Bern. August 2025.

Weak derivatives

There are numerous memes floating around with the words “Being weak is nothing to be ashamed of; staying weak is.” Or some variation. I thought about this meme in the context of weak derivatives.

Being weak is nothing to be ashamed of; staying weak is.

The last couple posts have talked about distributions, also called generalized functions. The delta function, for example, is not actually a function but a generalized function, a linear functional on a space of test functions.

Delta function meme

Distribution theory lets you take derivatives of functions that don’t have a derivative in the classical sense. View the function as a regular distribution, take its derivative as a distribution, and if this derivative is a regular distribution, that function is called a weak derivative of the original function.

You can use distribution theory to complete a space of functions analogous to how the real numbers complete the rational numbers.

To show that an equation has a rational solution, you might first show that it has a real solution, then show that the real solution is in fact a rational. To state the strategy more abstractly, to find a solution in a small space, you first look for solutions in a larger space where solutions are easier to find. Then you see whether the solution you found lies in the smaller space.

This is the modern strategy for studying differential equations. You first show that a differential equation has a solution in a weak sense, then if possible prove a regularity result that shows the solution is a classical solution. There’s no shame in finding a weak solution. But from a classical perspective, there’s shame in stopping there.

Related posts

ODE to Fisher’s transform

I was calculating a correlation coefficient this afternoon and ran into something interesting.

Suppose you have two uncorrelated random variables X and Y. If you draw, say, a thousand samples each from X and Y and compute Pearson’s correlation coefficient, you almost certainly will not get 0, though you very likely will get a small number.

How do you find a confidence interval around a correlation coefficient?

Sample correlation coefficient values do not follow a normal distribution, though the distribution is approximately normal if the population correlation is small. The distribution gets further from normal as the correlation gets close to 1 or −1.

Enter Fisher’s transformation. If you run the sample correlation coefficient r through the function

½ log((1 + r)/(1 − r)) = arctanh(r)

you get something that has a distribution closer to the normal distribution. You find a confidence interval for the transformed variable, then undo the transformation.

Now where did the Fisher transform come from?

I don’t know whether this was Fisher’s derivation, but Hotelling came up the following derivation. Assume you apply a transform G(r) to the correlation coefficient. Write an asymptotic expansion for the kurtosis κ3 and set the first term equal to zero. This leads to the ordinary differential equation

3(1 − r³) G″(r) − 6r G′(r) = 0

which has the solution G(r) = arctanh(r).

I found this interesting because I’ve worked with differential equations and with statistics, but I’ve rarely seen them overlap.