What exactly is modified about a modified Bessel function?

Special functions often have arcane names that not very helpful without some context. The previous post goes into some reasons for this. This post will expand on a point at the end of the post about “modified” functions.

Things are given their names for reasons. Discovering those reasons may help you understand their motivation and use.

Pure math perspective

For each integer n, the modified Bessel function In is essentially the Bessel function Jn evaluated along the imaginary axis. Specifically,
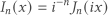
I_n(x) = i^{-n} J_n(ix)

From a certain shallow perspective, that’s the end of the story: modified Bessel functions are modified in the sense that the argument is multiplied by i. And there’s a fiddly constant term up front for no apparent reason.

But of course that’s not the end of the story or else this wouldn’t be worth an entire post.

The equation above is analogous to the relationships between circular and hyperbolic functions
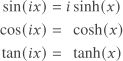
\begin{align*} \sin(ix) &= i \sinh(x) \\ \cos(ix) &= \phantom{i} \cosh(x) \\ \tan(ix) &= \phantom{i} \tanh(x) \end{align*}

These relationships are interesting because the circular and hyperbolic functions are independently meaningful. If you view these equations merely as definitions you lose their significance. Circular and hyperbolic functions were widely used before Euler discovered the connection between them.

Similarly, there’s a reason the modified Bessel functions were given a name their own. If you were led to Bessel functions and modified Bessel functions separately by different applications, you would regard the equation

I_n(x) = i^{-n} J_n(ix)

as a discovery rather than just a definition. The following section explains why someone would be interested in modified Bessel functions.

Before we move on, I’d like to explain the reason for the term i−n term. In general
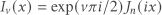
I_\nu(x) = \exp(\nu\pi i/2) J_n(ix)

for all real ν. The reason for the exp(νπi/2) term is that it makes Iν(x) real for all real x.

Applied math perspective

Bessel functions often arise from solving problems with radial symmetry. Solving the wave equation in cylindrical coordinates using separation of variables leads to Bessel’s differential equation

x^2 y'' + x y' + (x^2 - \nu^2) y = 0

and its solutions Jn and Yn, Bessel functions of the first and second kind.

Solving the heat equation in cylindrical coordinates with separation of variables leads to the modified Bessel equation
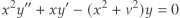
x^2 y^{\prime \prime} + x y^{\prime} - (x^2 + \nu^2) y = 0

and its solutions In and Kn, the modified Bessel functions of the first and second kind.

This is the reason behind the complex analysis perspective above: the change of variables sending x to ix changes the sign of the x² term in Bessel’s equation.

Bessel functions describe radially symmetric oscillations, such as the vibrations of a drum head. Modified Bessel functions describe radially symmetric exponential growth or decay [1], such as in the heat in a cylinder.

Other modified functions

Struve functions are closely related to Bessel functions. The (modified) Struve functions also satisfy Bessel’s (modified) differential equation, but with a non-zero right hand side. The modified Struve functions are proportional to the unmodified Struve functions evaluated along the imaginary axis, with a proportionality constant that makes the modified Struve functions real for real arguments.

There’s a similar relationship between the Mathieu functions and modified Mathieu functions. The general pattern is that “modified” in the context of special functions means “evaluated at ix and multiplied by a constant to make the function real for real arguments.”


[1] The functions In grow exponentially and the functions Kn decay exponentially. For this reason, A&S didn’t tabulate In and Kn per se. Instead it tabulated e−xIn and exKn because these functions varied less over their range.
Why special function terminology is arcane

Special functions are special because they’re useful. They can also be shrouded in arcane terminology. These two facts are related.

The more widely useful a function is, the more likely it is that the function will be discovered independently multiple times. Independent discoveries lead to varying definitions and notations. For example, there are two widely used definitions of Hermite polynomials, one used in probability and another used in physics, that only differ by a scaling factor. This also explains why there are so many variations on the definitions of the Fourier transform and spherical coordinates.

Special functions were discovered and applied before they were studied systematically. As with most mathematics, practice preceded theory. In hindsight, some names and conventions were less than ideal, at least from the perspective of someone seeking to organize a theory.

Functions can have arcane names for several reasons, one being that their usefulness became apparent long ago. If your instinct is that things with strange names are no longer important, your instinct might be backward. The strange name may be an indication that something is so important that its usefulness became apparent long ago.

Sometimes special functions have bland, uninformative names because the names stuck before anybody could think of something better. Bob looks into an interesting family of functions [1], then later he finds another interesting family of functions. These become known as “Bob’s functions of the first kind” and “Bob’s functions of the second kind.” These names are quite understandable at the time, though in the future people will want to know what distinguishes the functions, other than the fact that Bob discovered them, and what the groupings have in common other than the order in which Bob found them.

I started this post intending to discuss modified Bessel functions and explain what exactly is modified about them, but my preface became its own post. “Modified” is an example of the bland terminology mentioned above. There are Bessel functions and modified Bessel functions. Without more context, the “modified” term isn’t very informative. But it does provide a clue that there’s some kind of close relationship between the modified and unmodified functions. That’ll be the topic of my next post.


[1] Math education doesn’t place much emphasis on history and motivation. You may have to do some digging to find out why Bob was interested in his functions. What else was Bob known for? Maybe they’re related.

The difference orbit inclination makes

Suppose you wanted to find the distance between Earth and Mars over time. To first approximation, both planets orbit the sun in elliptic orbits in the same plane.

If you wanted to be more accurate, you’d need to take into account the fact that the orbit of Mars is tilted about 1.85° relative to the Earth’s orbit. How much difference does that make?

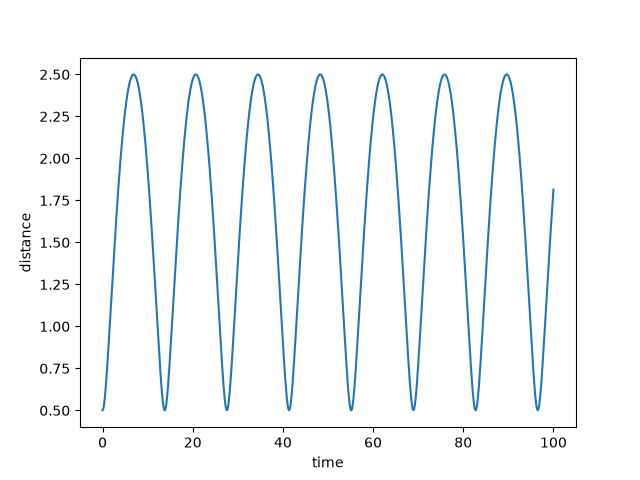
To simplify things, let’s assume the Earth orbits the sun in a circle of radius 1 and Mars orbits the sun in a circle of radius 1.5. The distance between Earth and Mars over time would be basically sinusoidal.

How much does inclination contribute to this distance? In other words, what is the difference between the distance accounting for the inclination of Mars’ orbit and the distance if we assume the two orbits are in the same plane?

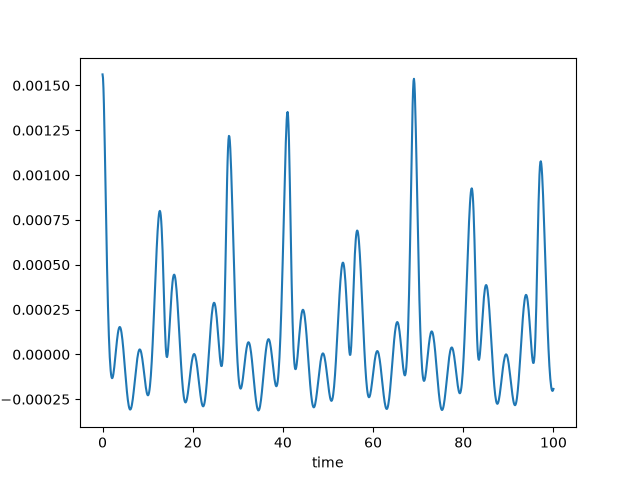
This plot gives the answer.

The effect is not large, about three orders of magnitude smaller than the main effect, but it’s interesting how erratic it is.

The plots were made with the following code.

from numpy import *

R = 1.5
T = R**1.5 # Kepler's third law

def f(t, theta):
    return sqrt(
        (cos(t) - R*cos(t/T)*cos(theta))**2 +
        (sin(t) - R*sin(t/T))**2 +
        (R*sin(theta)*cos(t/T))**2
    )

The first plot graphs f(t, θ) and the second graphs f(t, θ) − f(t, 0).

How would you know whether an ancient culture had zero?

A few weeks ago I wrote about the number system used in labeling spreadsheet columns. Labels run from A through Z, then AA through AZ, etc. This looks a lot like base 26, but it’s not quite the same. It has no analog of zero. If Z were like zero, Y would be followed by AZ. The Excel labeling system is not base 26, but what’s called bijective base 26.

If you found fragments of writing from an ancient culture and inferred that five symbols were used as digits, how could you distinguish base 5 from bijective base 5? Suppose you believe these five symbols were digits

★ ☂︎ ☘︎ ☗ ☢︎

but you don’t know in what order. You just see sequences like ☂︎☘︎☢︎ and ★★☂︎ and believe they’re numbers.

If you noticed that numbers often contain ☘︎, but ☘︎ never appears at the beginning of a number, you might infer that ☘︎ is a zero. But this would take a fairly large sample. If you found only 20 numbers, for example, you could hardly conclude ☘︎ never appears at the beginning of a number just because it doesn’t come at the beginning of any number you’ve seen.

Now suppose you’ve found writing with more number symbols. Say you’ve found 17 numeric symbols. You might infer that the writing used a base 20 system, because it would be hard to imagine a human culture using base 17. Now imagine you find more fragments and confirmed that indeed there are 20 numeric symbols. Approached as a purely statistical problem, you’d need a very large sample to infer what the digits correspond to and whether they use a base 20 or bijective base 20 system (or some other system).

You’re best hope is to find numbers in some context where you know what number is being represented. If you knew somehow that some symbol corresponds to 20, then you’d know they didn’t use base 20 because base b doesn’t have a single symbol for b.

If you had a huge collection of numbers but no context, which is highly unlikely, you could use Benford’s law to infer the meaning of the number symbols: the most common leading digit is probably 1, the next most common is probably 2, etc. This is interesting to think about, but it seems much more realistic that a number system would be decoded by finding context, such as a list of consecutive numbers or numbers with known meaning.


Big little hexagon

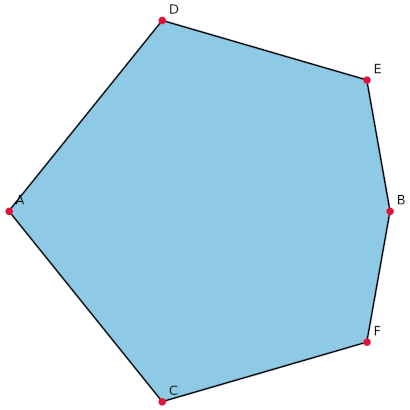
A new paper just came out, The Maximum-Area Small Polygon Problem. The paper solves the problem of finding, for each n, the n-gon with diameter 1 and maximum area.

For odd n, the solution is what you might expect: a regular n-gon. I would expect this to be the solution for even n as well, but it’s not.

In 1974 [1] Ron Graham found a solution for n = 6, a hexagon with unit diameter and area larger than a regular hexagon with unit diameter. Polygons with diameter ≤ 1 are called “small”, and he found the “largest” (i.e. maximum area) small hexagon.

The vertices of Graham’s hexagon are given below.

  A = (0.0000000000,  0.0000000000)
  C = (0.4023506913, -0.5000000000)
  F = (0.9390533483, -0.3437714489)
  B = (1.0000000000,  0.0000000000)
  E = (0.9390533483,  0.3437714489)
  D = (0.4023506913,  0.5000000000)

You can verify that the distance between any pair of vertices is no more than 1 and that the area of Graham’s hexagon is 0.674981.

The area of a regular hexagon of diameter 1 is (3/8)√3 = 0.649519, and the area of Graham’s hexagon is about 3.9% larger.

[1] R. L. Graham. The Largest Small Hexagon. Journal of Combinatorial Theory (A) 18, 165–170 (1975). The paper was submitted February 22, 1974 and published in 1975.

The imbalance theorem

The imbalance conjecture is now a theorem. James Alexander Schreib and Yousof Yavari posted a proof last week.

What does the conjecture theorem say? Start with a graph G with no edge between two nodes of the same degree. Then for every edge, calculate the absolute value of the difference of the degree of each end. The imbalance theorem says there exists another graph H whose vertices have degrees corresponding to the differences of degrees in G.

For example, let G be the graph below.

The edges from the top red vertex A to each of the blue vertices around it all have degree difference 5 because A has degree 6 and the vertices a0 to a4 have degree 1. The edge between the two red vertices, A and B, has degree difference 2. The remaining vertices have degree difference 3.

So the multiset of degree differences is

{5, 5, 5, 5, 5, 2, 3, 3, 3}

The imbalance theorem says there exists a graph H whose nodes have these degrees. Here is an example of such an H.

Note that in H, the 5 red nodes have degree 5, the single green node has degree 2, and the three blue nodes have degree 3.

More graph posts

Mean distance to the sun

Suppose you have a planet in an elliptical orbit around a star. The math is identical for any light object orbiting a heavy object, such as a moon or satellite orbiting a planet, but we’ll call the heavy object a star and the light object a planet.

The center of the star is not quite the center of the orbit. The planet moves along an ellipse with the star at one focus of that ellipse.

Let a be the semi-major axis of planet’s orbit, the maximum distance from the center of the ellipse to a point on the ellipse. Then the distance of a focus to the center of the ellipse is ae where e is the eccentricity of the ellipse. This defines eccentricity. The center of earth’s orbit is between three and four solar radii away from the center of the sun [1].

The planet is farthest from the star when it is along the major axis of the ellipse on the opposite side as the star. The distance is then a + ae, the distance to the center plus the distance from the center to the star. On the opposite side of its orbit, the planet is closest to the star. There the distance is a − ae. In summary the maximum distance to the star is

a(1 + e)

and the minimum distance is

a(1 − e).

If you had to guess the average distance between the planet and its star, a would be a good guess since it’s the average of the maximum and minimum distance. And that’s a good approximation, provided e is small. The mean distance over time is

a(1 + ½e²).

See derivation. The average distance is greater than a because the planet moves faster when nearest the star and slower when further from the star.

The relative error in approximating the mean distance by a is then ½e². When e is small, ½e² is very small. For the earth’s orbit, e = 0.01671, and so the approximation is off by around 0.014%.

The eccentricity of Pluto’s orbit is 0.2488, and so in that case the approximation is off by about 3.1%. The eccentricity of a Molniya orbit, used by some Russian satellites, is 0.74 [2]. For such satellites the error in approximating the mean distance to earth as the semimajor axis is around 27%.

Related posts

[1] For earth’s orbit, e = 0.01671, a = 1.496×10¹¹ m, and the sun’s radius is r = 6.957×10⁸ m. And so ea / r = 3.59.

[2] An object in such a highly elliptical orbit will spend a long time at the far side of its orbit, i.e. over Russia. Sort of a poor man’s geostationary orbit.

Proportion of 1s in a Hadamard matrix

The first post in the recent series of posts on Hadamard matrices describes a way of constructing new Hadamard matrices from two other Hadamard matrices by taking their Kronecker product.

Starting with a Hadamard matrix H0 and a Hadamard matrix G, you can construct a sequence of Hadamard matrices by

Hn+1 = G ⊗ Hn

for  positive integers n. This is known as the generalized Sylvester method.

Let pn be the proportion of 1s in Hn and let q be the proportion of 1s in G. Then you can show that the recurrence holds

pn+1 = q pn + (1 − q)(1 − pn).

You can solve the recurrence to show that

limn → ∞ pn = ½

and so as the iterations proceed, the ratio of number of 1s to the number of −1s approaches 1.

This doesn’t say anything Hadamard matrices in general, but it does apply to all Hadamard matrices created by repeatedly applying the generalized Sylvester method.

If you set G and H equal to the matrix

 \begin{bmatrix} 1 & 1\\ 1 & -1 \end{bmatrix}

then p0 = q = ¾. Then for n = 1, 2, 3, …, 8 the values of pn are

0.625
0.5625
0.53125
0.515625
0.5078125
0.50390625
0.501953125
0.5009765625.


Probability of correcting errors

Error correcting codes are most simply described in terms of the errors they can certainly correct. For example, the Hadamard code used for the Mariner 9 probe to Mars encoded each 6-bit pixel to a 32-bit codeword in such a way that the original pixel could be recovered if no more than 7 bits were corrupted in transit.

What is the probability that a pixel could be repaired if corrupted? That depends on your probability model. We will assume that the probability of each bit being flipped is p and that errors are independent.

(Are errors independent, i.e. if a bit flips, is the next bit more or less likely to flip? That would depend on context.)

It’s straight-forward to calculate the probability that 7 or fewer bits out of 32 flip; this is the cumulative distribution of a binomial random variable. The following Python code will return the probability of k or fewer successes out of n trials, each with probability of success p:

    from scipy.stats import binom
    print(binom.cdf(k, n, p))

For example, if there is a 10% chance that each bit will flip, there’s a 98.8% chance that 7 or fewer bits out of 32 will flip.

However this only gives a lower bound on the probability of correcting an error. If eight bits flip in transit, we cannot tell with certainty which codeword was sent, but there will be a couple possibilities that stand out. We’ll have to guess, but we’ve narrowed down the possibilities. With even more flipped bits, there’s always a chance of recovering the original data. Still, the lower bound captures most of the probability of recovery.

Now suppose you’re given a desired error recovery rate and have to determine what value of p it can sustain. For example, someone might say they want a 98.8% chance of recovering a pixel correctly, and you could come back and say p must be less than or equal to 0.1. This would be a conservative answer because as discussed above, p = 0.1 gives a pixel recovery probability of something more than 98.8, though it’s messy to calculate how much more.

You could solve for p by trial and error, or you could use some more sophisticated math to compute p directly. Given a probability F, you can solve for p such that the probability of up to k successes out of n trials using the inverse of the regularized incomplete beta function.

from scipy.special import betaincinv
p = 1 - betaincinv(n - k, k + 1, F)

Calculating F given n, k, and p could be a homework exercise in an introductory probability course. Solving for p given F, n, and k either requires some numerical programming or special functions and so would be a more challenging problem.

Related posts

Compressing a Hadamard matrix

Hadamard matrices are in the news following the recent announcement of a newly discovered Hadamard matrix. I’ve written three posts on Hadamard matrices recently, one as a sort of introduction and two on applications: the error correcting code used in the Mariner 9 probe and constructing sphere packings.

A Hadamard matrix is an orthogonal matrix with all entries equal to ±1. Jacques Hadamard conjectured that there exist Hadamard matrices of order 4n for all positive integers n. It’s necessary that the order be divisible by 4, and Hadamard conjectured that this is sufficient [1].

How could you compactly represent a Hadamard matrix? Since the entries are all either 1 or − 1 each entry could be represented by a single bit, and n² bits could store an n × n Hadamard matrix. But we can do better.

Methodical matrices

If the matrix can be produced by an algorithm, you only need to store the name of the algorithm and the argument to the algorithm. So, for a 1024 × 1024 matrix applied by iterating Sylvester’s algorithm could be stored by saying “Apply Sylvester’s algorithm 10 times” rather than storing a megabyte of data.

Paley’s method can create a Hadamard matrix corresponding to every prime power. So you could determine a Paley type matrix by storing the prime and the exponent.

Next in complexity would be hybrid algorithms, such as start with the Paley method applied to 376 and then apply Sylvester’s method 3 times.

There are more methods of creating Hadamard matrices than Sylvester’s method and Paley’s method, though they’re harder to describe and parameterize.

Sporadic matrices

If a Hadamard matrix cannot be constructed using an algorithm, you can still store the matrix in fewer than n² bits. Since the rows are orthogonal, the last row of the matrix is determined by all the previous rows, up to sign. So you could store a Hadamard matrix using n(n − 1) + 1 bits.

Some Hadamard matrices are symmetric or skew. A symmetric matrix is determined by its diagonal and the elements above the diagonal. So a symmetric Hadamard matrix could be represented by n(n + 1)/2 bits.

A skew Hadamard matrix isn’t quite skew-symmetric. A matrix M is skew symmetric if

MT = −M.

This implies the diagonal elements are 0, and Hadamard matrices cannot contain 0s. A Hadamard matrix H is called skew if

H + HT = 2I.

This implies the diagonal elements are all 1s and the elements below the diagonal have the opposite sign of the elements above the diagonal. Since the elements on the diagonal are determined, a skew Hadamard matrix can be sorted using n(n − 1)/2 bits.

Incidentally, there is a conjecture that there exist skew Hadamard matrices of order 4n for all positive n.


[1] There are Hadamard matrices of order 1 and 2, but larger orders must be divisible by 4.