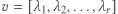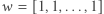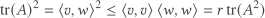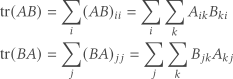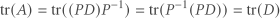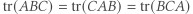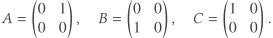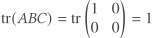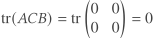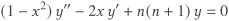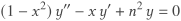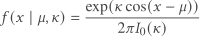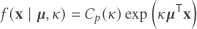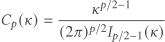Fibonacci product

The product of four consecutive Fibonacci numbers equals the product of two consecutive integers.

For example,

3 × 5 × 8 × 13 = 39 × 40.

I ran across this theorem in a note [1] that says “The product of any four consecutive Fibonacci numbers is twice a triangular number.” Since triangular numbers have the form n(n + 1)/2, twice a triangular number is the product of two consecutive integers.

The note also gives a way to find the numbers on the right hand side. We have

Fn Fn+1 Fn+2 Fn+3 = m(m + 1)

where m equals

Fn+1 Fn+2

if n is odd and

Fn Fn+3

if n is even.

In the example at the top, 3 is the 4th Fibonacci number, so n = 4. Since 4 is even, m is the product of the 4th and 7th Fibonacci numbers, i.e. m = 3 × 13 = 39.

More Fibonacci posts

[1] K. B. Subramaniam. On a link between Triangular and Fibonacci numbers. The Mathematical Gazette, Vol. 103, No. 558 (November 2019), p. 489.

Simple approximation for spherical cap area

The previous post looked at how to interpret cosine similarity, or equivalently angles between word vectors. In a high-dimensional space, randomly chosen vectors are likely nearly perpendicular, and so relatively large angles, such as 50°, indicate very closely related words.

Another way to look at this, as explained in the previous post, is that in high dimensions, a spherical cap of angular radius θ represents a small portion of a sphere, even for moderately large θ.

The proportion of the area inside the spherical cap, given here, involves the “regularized incomplete beta function” and so it’s hard to have an intuition for the value.

For large dimension n, the approximation

n−1/2 sinn − 1(θ)

gives the proportion of the area inside the cap to within an order of magnitude. It’s easy to see that this function goes to zero quickly as n increases, provided |θ| < π/2.

If you have the cosine similarity c = cos θ rather than θ itself, the approximation becomes

n−1/2 (1 − c²)(n − 1)/2.

Python script

Let’s try it on the example from the previous post, in which n = 200 and θ = 49°.

import numpy as np
from scipy.special import betainc

# Fraction of S^{n-1} inside a spherical cap of angular radius theta
# theta is measured from the pole
# Assume 0 < theta < pi/2

def cap_fraction(theta, n):
    x = np.sin(theta) ** 2
    return 0.5 * betainc(0.5 * (n - 1), 0.5, x)

def cap_fraction_approx(theta, n):
    return n**(-0.5) * np.sin(theta)**(n-1)

theta = np.deg2rad(49)
print(cap_fraction(theta, 200)) 
print(cap_fraction_approx(theta, 200)) 

This prints 2.03e-26 and 3.37e-26. The order of magnitude is correct as advertised.

Navier-Stokes in the news

There are rumors that a long-standing math problem, one of the Millennium Prize problems, has been solved.

The problem concerns technical properties of solutions to the Navier-Stokes equations [1], a set of equations that describe the dynamics of fluid flow. Popular accounts of the problem are often oversimplified and misleading.

Some reports will speak of the problem as “solving the Navier-Stokes equations.” The task is not to write down a closed-form solution, which can’t be done, or solve the equations numerically, which has been done for decades. The problem is to prove theoretical properties of solutions which are of little interest in practice.

There has been progress toward settling the Navier-Stokes problem. Terence Tao wrote a post on this yesterday.

What’s also  interesting is the intrigue around the possible solution. A post this morning says

If I am reading this correctly, Tristan Buckmaster is alleging OAI has a resolution of Navier-Stokes … which maybe used info from Buckmaster and Levent Alpöge’s private Codex sessions.

Buckmaster asked OpenAI whether they used his private sessions and they have not responded. Update: Statement from OpenAI.

Personal note

This topic connects parts of my career spanning decades. My graduate work was in PDEs and I had some interest in the Navier-Stokes equations. Here are some notes I wrote back in the day.

Now I work more with privacy than with PDEs. The question of whether OpenAI uses private data, contradicting their stated policy, is more relevant to my current work than whether the Navier-Stokes equations have global regular solutions.

Related posts

[1] I never know whether to say equation or equations. You’ll hear both. You could think of Navier-Stokes as one vector-valued PDE or three scalar-valued equations.

Proof of the rank-trace theorem

The previous post discussed the motivation for and application of the rank-trace theorem. This post will give a proof.

Suppose A is a real symmetric matrix. The rank-trace inequality says

\operatorname{rank}(A)\ge\frac{(\operatorname{tr} A)^2}{\operatorname{tr}(A^2)}

where tr is the trace operator, the sum of the elements along the diagonal of the matrix.

Terse proof

Here’s the proof in a nutshell: diagonalize A and use the Cauchy-Schwarz inequality.

Detailed proof

Now let’s unpack that. Any real symmetric matrix A is similar to a matrix D with the eigenvalues of A along the diagonal.

A = PDP^{-1}

The trace of a matrix stays the same under a similarity transformation, i.e. multiplying by P on one side and its inverse on the other side. So without loss of generality we may as well assume A is diagonal.

The rank of a matrix equals the number of non-zero eigenvalues, so a vector containing the non-zero eigenvalues of A

v = [\lambda_1, \lambda_2, \ldots, \lambda_r]

has length r where r is the rank of A. Define w to be the vector of dimension r consisting of all 1’s.

w = [1, 1, \ldots, 1]

Then by the Cauchy-Schwarz inequality we have

\operatorname{tr}(A)^2 = \langle v, w \rangle^2 \leq \langle v, v \rangle \, \langle w, w \rangle = r \operatorname{tr}(A^2)

Cyclic trace property

Why should a matrix A and its diagonalization D have the same trace?

The trace of a matrix product AB equals the trace of the product BA. To prove this, write out matrix products and the traces, then note that the two expressions are equal.

 \begin{align*} \operatorname{tr}(AB) &= \sum_i(AB)_{ii}=\sum_i\sum_k A_{ik}B_{ki} \\ \operatorname{tr}(BA) &= \sum_j(BA)_{jj}=\sum_j\sum_k B_{jk}A_{kj} \end{align*}

Therefore

\operatorname{tr}(A) = \operatorname{tr}((PD)P^{-1}) = \operatorname{tr}(P^{-1}(PD)) = \operatorname{tr}(D)

More generally, trace has the cyclic property

\operatorname{tr}(ABC) = \operatorname{tr}(CAB) = \operatorname{tr}(BCA)

However, not all permutations preserve the trace. For example, let

A=\begin{pmatrix}0&1\\0&0\end{pmatrix},\quad B=\begin{pmatrix}0&0\\1&0\end{pmatrix},\quad C=\begin{pmatrix}1&0\\0&0\end{pmatrix}.

Then

\operatorname{tr}(ABC) = \operatorname{tr}\begin{pmatrix}1&0\\0&0\end{pmatrix} = 1

but

\operatorname{tr}(ACB) = \operatorname{tr}\begin{pmatrix}0&0\\0&0\end{pmatrix} = 0

Computing a lower bound on matrix rank

Suppose you want to know the rank of an n × n matrix A, the number of linearly independent rows of A, or equivalently the number of linearly independent columns. There are at least three difficulties.

Difficulties in computing rank

First of all, rank is not a continuous function of a matrix. Since rank is an integer, an arbitrarily small change in the matrix could cause a discrete change in the rank [1]. A small error in computing A could produce a matrix with a different rank.

Second, finding the rank takes O(n³) operations, which may or may not be an issue depending on context.

Third, you may not have the matrix A in an explicit form. Maybe you’re able to compute products Av for vectors v but it’s not practical to form the entire matrix A.

Rank-trace inequality

If you don’t need to know the rank of A per se, but only need to know whether it is above a certain size, a lower bound on the rank may enough.

Suppose A is a Hermitian matrix. If A is real, this means A is symmetric. If A is complex, this means A equals its conjugate transpose. Then the rank-trace inequality says
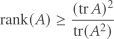
\operatorname{rank}(A)\ge\frac{(\operatorname{tr} A)^2}{\operatorname{tr}(A^2)}
The quantity on the right hand side is known as the stable rank of A. It’s not a rank in any algebraic sense, but it gives a lower bound on rank. And it solves the three problems listed above. See the next post for a proof of the rank-trace theorem.

Stability

First of all, trace is a continuous function of a matrix, and so stable rank is also a continuous function of a matrix, provided the denominator isn’t zero. A small change to a matrix only makes a small change to its stable rank. That’s why stable rank is called stable.

Efficiency

Second, although computing rank takes O(n³) operations, computing stable rank takes only O(n²) operations, though this isn’t immediately obvious.

The trace of A takes n operations: simply sum the elements on the diagonal of A. But how do you take the trace of A²? Squaring A takes n³ operations, and so if you had to square A to find the trace of A² the rank-trace inequality would have no efficiency advantage over finding the rank of A. But you can compute the trace of A² via
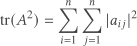
\operatorname{tr}(A^2) = \sum_{i=1}^n \sum_{j=1}^n |a_{ij}|^2

Formation

Now suppose you don’t have the matrix A per se but you do have a way of probing A, computing the product of vectors with A. Maybe A is too large to fit into memory, or explicitly computing the elements of A would take too long.

There are Monte Carlo algorithms for estimating the traces of A and A² that could be used together to estimate the stable rank of A.

Demonstration

The following Python code illustrates the discussion above.

import numpy as np

np.random.seed(20260904)
n = 5
B = np.random.randn(n, n)
A = B.T @ B + 1e-8 * np.eye(n)  # Gram matrix plus a tiny shift => SPD

rank_A = np.linalg.matrix_rank(A)
tr_A = np.trace(A)
tr_A2 = np.trace(A @ A) # matrix product 
sum_sq = np.sum(A * A) # element-by-element product
stable_rank = (tr_A ** 2) / tr_A2

print(f"A =\n{A}\n")
print(f"rank(A)              = {rank_A}")
print(f"tr(A)                = {tr_A:.12f}")
print(f"tr(A^2) direct       = {tr_A2:.12f}")
print(f"tr(A^2) indirect     = {sum_sq:.12f}")
print(f"stable rank          = {stable_rank:.12f}")

The code above produces the output below.

A =
[[ 1.09945682  0.4899665   0.98901845  0.66983113 -1.35006341]
 [ 0.4899665   0.98531254  0.35067791  0.89757603 -0.72037507]
 [ 0.98901845  0.35067791  4.31233926  0.94556225 -0.54819048]
 [ 0.66983113  0.89757603  0.94556225  1.3494295  -1.33840786]
 [-1.35006341 -0.72037507 -0.54819048 -1.33840786  3.54858332]]

rank(A)              = 5
tr(A)                = 11.295121449420
tr(A^2) direct       = 51.035447533673
tr(A^2) indirect     = 51.035447533673
stable rank          = 2.499826585688

[1] Topological argument: A map from a connected space (such as ℝn×n) onto a discrete space (such as ℤ) cannot be continuous, otherwise the inverse images of the points in the range would partition the connected space into disjoint open sets, violating the definition of a connected space.

Second solutions

This post provides a couple examples to go along with two earlier posts.

The pattern we’re illustrating is families of polynomials pn(x) that each satisfy a differential equation and a three-term recurrence. The differential equations have a second solution qn(x) that is the larger solution with respect to x but the smaller solution with respect to n.

In both the examples below pn(x) is a polynomial, and so bounded on the interval [−1, 1], and qn(x) is not a polynomial, with singularities at ±1. This is analogous to the previous examples with Bessel functions Jn(x) and Qn(x) that satisfy the same differential equation but have contrasting behavior with respect to x versus n.

Legendre polynomials

The differential equation

(1-x^2)\,y^{\prime\prime} - 2x\,y^\prime + n(n+1)\,y = 0

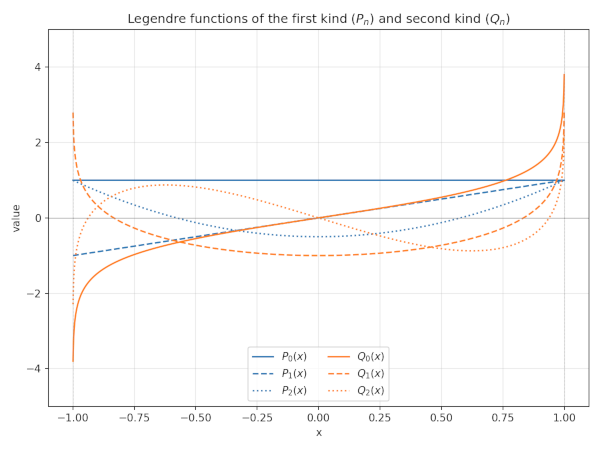
has two solutions for each n, Pn(x) and Qn(x).

The solutions Pn(x) are the Legendre polynomials. The solutions Qn(x) are not polynomials but involve a term log((1 + x)/(1 − x)) that blows up at 1 and −1. But for fixed x and increasing n, Pn(x) grows exponentially and Qn(x) decays exponentially, provided |x| > 1.

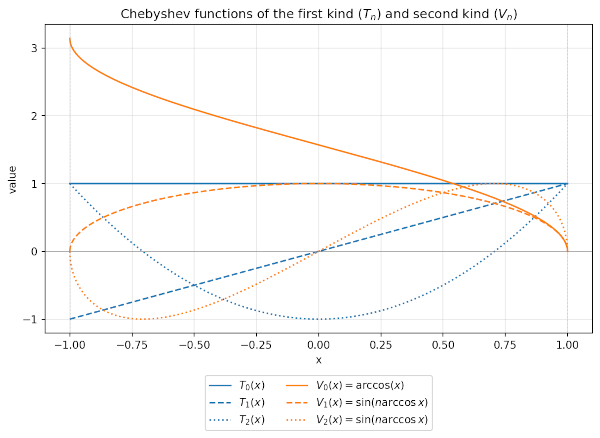
Chebyshev polynomials

The differential equation

(1-x^2)\,y^{\prime\prime} - x\,y^\prime + n^2\,y = 0

has two solutions for each n, Tn(x) and Vn(x).

The solutions Tn(x) are the Chebyshev polynomials. The solutions Vn(x) are not polynomials but involve a term √(x² — 1) that become vertical up at 1 and −1. But for fixed x with |x| > 1 and increasing n, Tn(x) grows exponentially and Vn(x) decays exponentially.

Junk solutions

When you’re interested in studying a family of functions, it can be useful to look at a differential equation that the functions solve. This is a theme I’ve written about several times, most recently here and here, but also three years ago here.

Orthogonal polynomials are mathematically elegant as well as very useful in applications [1]. Various families of orthogonal polynomials satisfy various differential equations. These equations have a polynomial and non-polynomial solutions. What use are the latter?

If the differential equation modeled something physical, then the second solution would be necessary to have a complete basis of solutions. But if the differential equation is only instrumental in studying the orthogonal polynomials, what use is a non-polynomial solution?

These non-polynomial solutions turn out to be useful. Just as “junk” DNA turned out not to be junk, these “junk” solutions are important. Junk DNA doesn’t directly code for proteins, but it regulates DNA that does code for proteins and serves other purposes. Similarly, these non-polynomial solutions carry information related to the polynomial solutions.

For example, orthogonal polynomials are used to construct numerical integration methods, such as Gaussian quadrature, and the associated non-polynomial solutions describe the error in these integration methods. Incidentally, Gaussian quadrature is based on Legendre polynomials, mentioned in the previous post. For every family of orthogonal polynomials there is a corresponding integration method. See these notes.

Another tie-in to recent posts is that these non-polynomial solutions are the minimal solution to the polynomial family’s three-term recurrence, the solution that takes extra care to compute numerically.

This post has been very high-level, alluding to ideas without going into details. I’d like to write future posts that go into more depth regarding the ideas introduced here.


[1] “Real analysts cannot do without Fourier, complex analysts cannot do without Laurent, and numerical analysts cannot do without Chebyshev [polynomials].” — Lloyd N. Trefethen”

Ultraspherical

When I hear the term ultraspherical I think of something extremely spherical. For example, a baseball is spherical, but a billiard ball is more spherical. Maybe a highly polished billiard ball is ultraspherical.

Using this line of thought, the term ultraspherical polynomial is inexplicable. This is an example of the arcane terminology I wrote about recently. In this post I’ll explain what it conveys.

A spherical polynomial is a polynomial that naturally falls out of solving Laplace’s equation in spherical coordinates, using separation of variables. Legendre polynomials are spherical polynomials.

Gegenbauer polynomials are so called because a man named Gegenbauer studied them, just as Legendre polynomials take their name from Legendre. Gegenbauer polynomials are also called ultraspherical polynomials. Why is that?

There are two possible reasons. I’m not sure which is the historical reason, but both are plausible and are useful mnemonics.

Ultraspherical polynomials are not extremely spherical, they’re beyond spherical in some sense. More modern terminology uses the hyper- prefix rather than ultra-, which helps a bit.

Ultraspherical polynomials are beyond spherical in two ways. Gegenbauer polynomials are a generalization of Legendre polynomials, so they’re beyond Legendre polynomials in this sense.

More importantly, Gegenbauer polynomials fall out of solving Laplace’s equation on a hypersphere, i.e. a sphere in ℝn for n > 3, just as Legendre polynomials fall out of the case n = 3. It makes sense to call these polynomials hyperspherical because they fall out of solving an equation on a hypersphere. Unfortunately the classical term is ultraspherical rather than hyperspherical.

I think, but I’m not sure, that at one time higher dimensional spheres were called hyperspheres, but the the higher dimensional analog of spherical coordinates was called ultraspherical coordinates. If so, it would be understandable that the adjective modifying coordinates would be applied to the polynomials that result from solving equations in these coordinates.

Numerical (in)stability of recurrence relations

The previous post gave several examples of three-term recurrence relations for special functions. These relations can be computationally useful, but they have to be applied carefully.

Several years ago I wrote a post on stable and unstable recurrences. In that post I show that the stability of the recurrence relation for Bessel functions produces depends on which kind of Bessel function and which direction the recurrence is applied.

In the forward direction, computing higher order values from lower order values, works well for Bessel functions of the second kind Yn but not for Bessel functions of the first kind Jn. In the reverse direction, the recurrence is stable for Jn but not for Yn.

I didn’t explain in that post why this is. In this post I will.

Second order linear difference equations have two independent solutions, just like second order linear differential equations. For both kinds of equations, all solutions are linear combinations of the two solutions. Suppose one solution grows with n and the other decays. You may want to compute the decaying solution, but in doing so you might pick up a small component of the growing solution due to rounding error. This post illustrates this phenomena for differential equations, and this post illustrates it for difference equations.

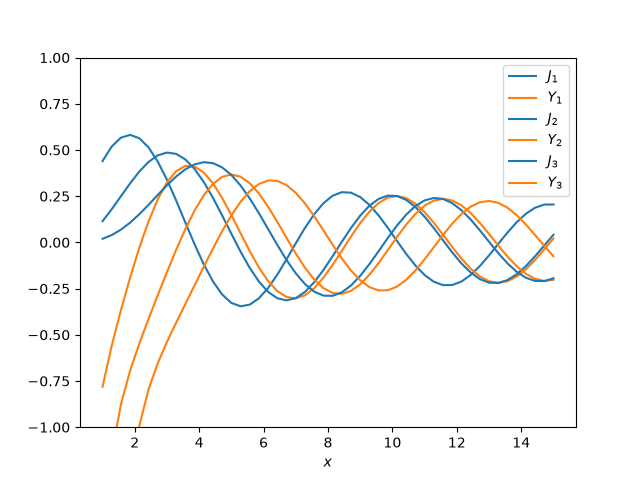
When you look at a plot of Bessel functions in a text book, you’ll probably see a few plots of Jn(x) andYn(x) for a few small values of n. The functions seem to behave roughly the same way, like sine and cosine. And that’s true, as functions of x.

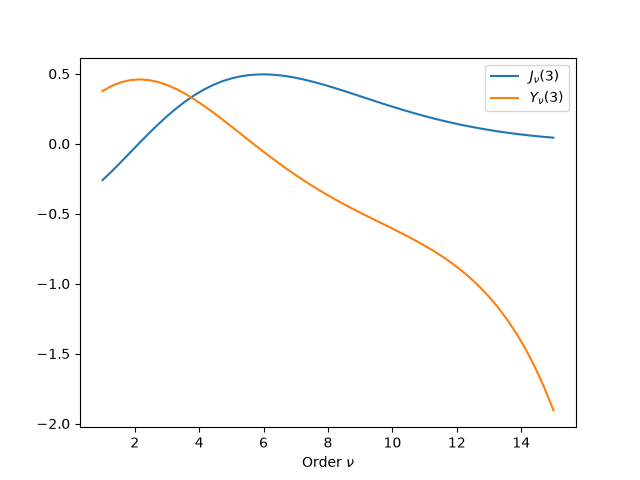
But it’s not true for Jn(x) andYn(x) as functions of n for fixed x. As n increases, Jn(x) decays to zero and Yn(x) goes off to −∞.

That’s the source of numerical instability. And there will be similar instability problems for other recurrences where the ratios of the two independent solutions goes to zero or infinity as a function of n.

There are techniques for computing the solution that does not diverge, the so-called minimal solution, such as Miller’s algorithm mentioned here.


The von Mises-Fisher distribution

Probability density function must integrate to 1, and so if you know a density function up to a constant, the constant is determined.

When you’re looking at a probability density f(x) for the first time, it helps to ignore the normalizing constant. Concentrate on the part of the function involving x and know that the normalizing constant is whatever it has to be. For example, about half of the ink that it takes to write down a beta or chi-squared density is devoted to the normalization constant; the rest of the expression is easier to understand.

This post will do the opposite of the advice above and focus on normalization constants because this ties into the previous post on modified Bessel functions.

The von Mises probability distribution on a circle has two parameters, μ and κ, and its density function is

f(x \mid \mu, \kappa) = \frac{\exp(\kappa \cos(x - \mu))}{2\pi I_0(\kappa)}

The normalizing constant is 2π I0(κ). The factor of 2π is unsurprising for anything defined on a circle. The more interesting part is I0, the modified Bessel function of order 0.

The von Mises-Fisher distribution is the generalization of the von Mises distribution to a sphere in p dimensions. The density function is

f(\mathbf{x} \mid \boldsymbol{\mu}, \kappa) = C_{p}(\kappa) \exp \left( {\kappa \boldsymbol{\mu}^\mathsf{T} \mathbf{x} } \right)

where the normalization constant Cp(κ) is

C_{p}(\kappa)=\frac {\kappa^{p/2-1}} {(2\pi)^{p/2}I_{p/2-1}(\kappa)}

where Ip/2 − 1 is the modified Bessel function of order p/2 − 1. The values of x and μ are in bold face because they are now vectors, points on the unit sphere.

When p = 2, we have the “sphere” in two dimensions, i.e. the circle, and the von Mises-Fisher distribution reduces to the von Mises distribution. But where did the cosine go? The inner product of x and μ is the cosine of the angle between the two vectors.

When p = 3, obviously an important special case, the von Mises-Fisher distribution is known as the Fisher distribution. In that case the normalizing constant C3(κ) can be written without using modified Bessel functions because when ν = ½ + n for an integer n, Iν(x) is an elementary function.