Impersonating an Edwardian math professor

I’ve read some math publications from around a century or so ago, and I wondered if I could pull off being a math professor if a time machine dropped me into a math department from the time. I think I’d come across as something of an autistic savant, ignorant of what contemporaries would think of as basic math but fluent in what they’d consider more advanced.

There are two things in particular that were common knowledge at the time that I would be conspicuously ignorant of: interpolation tricks and geometry.

People from previous eras knew interpolation at a deeper level than citing the Lagrange interpolation theorem, out of necessity. They learned time-saving tricks have since been forgotten.

The biggest gap in my knowledge would be geometry. Mathematicians a century ago had a far deeper knowledge of geometry, particularly synthetic geometry, i.e. geometry in the style of Euclid rather than in the style of Descartes.

Sometimes older math books use notation or terminology that has since changed. I imagine I’d make a few gaffs, not immediately understanding a basic term or using a term that wasn’t coined until later.

If I had to teach a class, I’d choose something like real and complex analysis. Whittaker & Watson’s book on the subject was first published in 1902 and remains a common reference today. The only thing I find jarring about that book is that “show” is spelled “shew.” Makes me think of Ed Sullivan. But I think I’d have a harder time teaching a less advanced class.

Related posts

Floating point: Everything old is new again

In the early days of computing hardware (and actually before) mathematicians put a lot of effort into understanding and mitigating the limitations of floating point arithmetic. They would analyze mundane tasks such as adding a list of numbers and think carefully about the best way to carry out such tasks as accurately as possible.

Now that most arithmetic is carried out in double precision, you can often get away with not thinking about such things. Except when you can’t. The vagaries of floating point computation still matter occasionally, even with double precision, though not as often as they did with single precision.

Although most computing has moved from single precision to double precision, there is increasing interest in going the opposite direction, from single precision to half precision. The main driver is neural networks. You don’t need a lot of precision in weights, and you’ve got a lot of numbers to store. So instead of taking 64 bits to store a double precision number, or 32 bits to store a single precision number. you might want to use a 16 bit or even 8 bit floating point number. That way you can fit more weights in memory at once.

However, when you move to lower precision numbers, you now have to think again about the things numerical analysts thought about a couple generations ago, such as different ways of rounding. You might think that floating point rounding could be modeled by random variables. If so, you’re in good company, because John von Neumann suggested this in 1947. But a few years later people began to realize that floating point rounding errors are not random. Or to be more precise, they began to realize that modeling rounding errors as random was inadequate; of course they knew that rounding errors weren’t literally random.

But what it rounding errors were random? This would lead to more error cancellation than we see in practice with floating point arithmetic. With stochastic rounding, the rounded values become unbiased estimators of the values they would like to represent but cannot represent exactly. Now the central limit theorem and all that come to your aid. More on applications of stochastic rounding here.

(To be pedantic a moment, stochastic rounding isn’t truly random, but uses pseudorandom numbers to implement a procedure which is well modeled by randomness. Random is as random does.)

Related posts

Birthday problem approximation

The birthday problem is a party trick with serious practical applications. It’s well known to people who have studied probability, but the general public is often amazed by it.

If you have a group of 23 people, there’s a 50-50 chance that at least two people have the same birthday. With a larger group, say 30, its quite likely two birthdays are the same. Not only is this a theoretical result, based on certain modeling assumptions, it actually works in practice, essentially as predicted.

Variations of the birthday problem come up routinely in applications. For example, in cryptography it’s important to know the probability of secure hash collisions. Hash functions are deterministic, but for practical purposes they act random. If you are hashing into a space of N possible hash values, you can expect to compute about √N items before two items have the same hash value.

The square root rule of thumb is very useful. For example, if you’re computing 128-bit hash values, there’s about a 50-50 chance of seeing two duplicate hash values after hashing about 264 items.

The square root heuristic works well for large N, but gives mediocre results for N as small as 365. When applied to the original birthday problem, it predicts even odds for seeing a pair of equal birthdays in a group of 19 people. That’s a little low, but not too far off.

As useful as the square root rule is, it is only good for finding when the probability of duplication is 1/2. What if you’d like to know when the probability of a collision is, say, 0.01?

Let N be the number of possible options and let r be the number of items chosen independently from the set of N options. Let P(N, r) be the probability that all r choices are distinct. Then

P(N, r) ≈ exp( −r²/2N).

This approximation [1] is valid when N is large and r is small relative to N. We could be more precise about the error bounds, but suffice it to say that bigger N is better.

When N = 365 and r = 23, the approximation above computes the probability that all 23 choices are distinct as 0.48, matching the canonical birthday problem and showing an improvement over the square root heuristic.

Related posts

[1] Anthony C. Robin. The Birthday Distribution: Some More Approximations. The Mathematical Gazette, Vol. 68, No. 445 (October, 1984), pp. 204–206

(1 − z) / (1 + z)

“I keep running into the function f(z) = (1 − z)/(1 + z).” I wrote this three years ago and it’s still true.

This function came up implicitly in the previous post. Ramanujan’s excellent approximation for the perimeter of an ellipse with semi-axes a and b begins by introducing

λ = (ab)/(a + b).

If the problem is scaled so that a = 1, then λ = f(a). Kummer’s series for the exact perimeter of an ellipse begins by introducing the same variable squared.

As this post points out, the function f(z) comes up in the Smith chart from electrical engineering, and is also useful in mental calculation of roots. It also comes up in mentally calculating logarithms.

The function f(z) is also useful for computing the tangent of angles near half a right angle because

tan(π/4 − z) ≈ f(z)

with an error on the order of z³. So when z is small, the error is very, very small, much like the approximation sin(x) ≈ x for small angles.

Error in Ramanujan’s approximation for ellipse perimeter

Ramanujan discovered an incredibly accurate approximation for the perimeter of an ellipse. This post will illustrate how accurate the approximation is and push its limits.

As with all computations involving ellipses, the error of Ramanujan’s approximation increases as eccentricity increases. But the error increases slowly, asymptotically approaching an upper bound that is remarkably small.

Let a and b be the semi-major and semi-minor axes of an ellipse. Then Ramanujan’s approximation for the perimeter of the ellipse is

\pi (a + b) \left(1 + \frac{3\lambda^2}{10 + \sqrt{4 - 3\lambda^2}}\right)

where λ = (ab)/(a + b).

Example

To illustrate how accurate the approximation is, let’s apply it to a very large, highly eccentric ellipse: the orbit of Sedna, a dwarf planet discovered in 2003. Sedna has the most elliptical orbit of any of the dwarf planets, 0.8496 compared to 0.2488 for Pluto. Sedna is also about 12 times further from the sun than Pluto.

The semi-major axis of Sedna’s orbit is 76 billion kilometers. Eccentricity e corresponds to aspect ratio √(1 − e²) (see this post), and so the semi-minor axis is about 40 billion kilometers. Let’s assume the orbit of Sedna is perfectly elliptical, which it is not, and that the semi-axes stated above are exact, which they are not. Then the length of Sedna’s orbit is on the order of 366 billion kilometers, and Ramanujan’s approximation has an error of about 53 kilometers.

Error

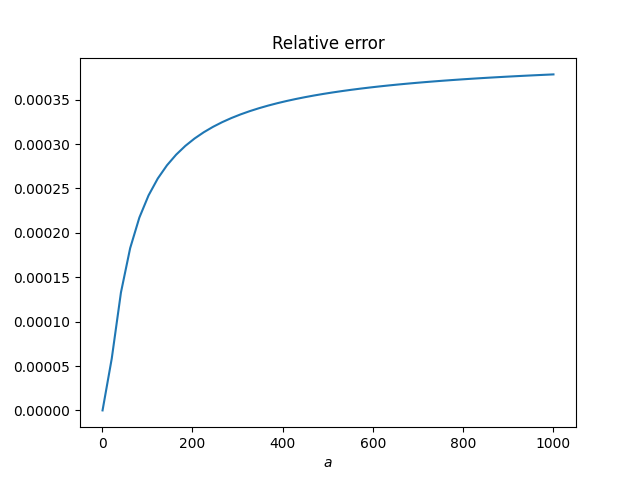
Here’s a plot of the relative error when b = 1 and a varies.

The error appears to be approaching an asymptote, and in fact it is. The error is bound by 4/π − 14/11 = 0.00051227…., as proved here.

Moments of inertia mnemonic

Edward John Routh (1831–1907) came up with a mnemonic for summarizing many formulas for moment of inertia of a solid rotating about an axis through its center of mass.

Routh’s mnemonic is

I = MS / k

where M is the mass of an object, S is the sum of the squares of the semi-axes, and k is 3, 4, or 5 depending on whether the object is rectangular, elliptical, or ellipsoidal respectively.

This post will show how a variety of formulas fit into Routh’s framework.

Rectangular solids

Suppose we have a box whose base is a rectangle of with sides of length a and b, and we’re rotating the box about the vertical axis through the center of mass. The moment of inertia is

I = M(a² + b²) / 12.

The semi-axes have length a/2 and b/2 and so the formula above fits into Routh’s mnemonic with k = 3:

I = M( (a/2)² + (b/2)² ) / 3.

Why did Routh state his theorem in terms of semi-axes rather than axes? Because circles and spheres are typically described in terms of radius, and ellipses are described in terms of semi-axes.

Cylinders

The moment of inertia for a (circular) cylinder about its center is

I = Mr² /2.

From Routh’s perspective, there are two perpendicular axes to the central axis, both of length r. So his mnemonic could calculate the moment of inertia as

I = M(r² + r²)/4

using k = 4.

For an elliptical cylinder, where the ellipse has semi-major axis a and semi-minor axis b, the moment of inertia is

I = M(a² + b²)/4

which reduces to the circular cylinder result when a = b = r.

Spheres and ellipsoids

The moment of inertia of a sphere about a line through its center is

I = 2Mr² / 5.

Again there are two perpendiculars to the line, both of length r, and so we get the result above using Roth’s mnemonic with k = 5.

For an ellipsoid with semi-axes a, b, and c, rotated about the axis corresponding to c, the moment of inertia is

I = M(a² + b²)/5.

Thin rod

The moment of inertia for a thin rod of length L rotated about its center is

I = ML²/3.

This can be derived from the case of a rectangular solid with length L and negligible width.

Note that the formula for moment of inertia of a cylinder does not apply because we are rotating the rod about its middle, not along the axis running the length of the rod.

Routh’s stretch rule

Moving a point mass in a direction parallel to the axis of rotation doesn’t change its moment of inertia. The continuous version of this observation means that we can stretch the shapes without changing their inertia if we stretch them in the direction of the axis of rotation. This means the rules above apply to more general shapes.

Related posts

Note the that this post refers to physical moments and the link above refers to statistical moments. They’re closely related.

Binomial bound

I recently came across an upper bound I hadn’t seen before [1]. Given a binomial coefficient C(r, k), let

n = min(k, rk)

and

m = r −  n.

Then for any ε > 0,

C(n + m, n) ≤ (1 + ε)n + m / εn.

The proof follows quickly from applying the binomial theorem to (1 + ε)n + m.

I could imagine how non-optimal choice of ε could be convenient in some context, it’s natural to want to see how good the upper bound is for the best ε, which works out to be ε = n/m.

A little algebra shows this value of ε leads to

C(n + m, n) ≤ (n + m)n + m / nn mm.

Note that while the original bound is not symmetric in n and m, the optimal bound is.

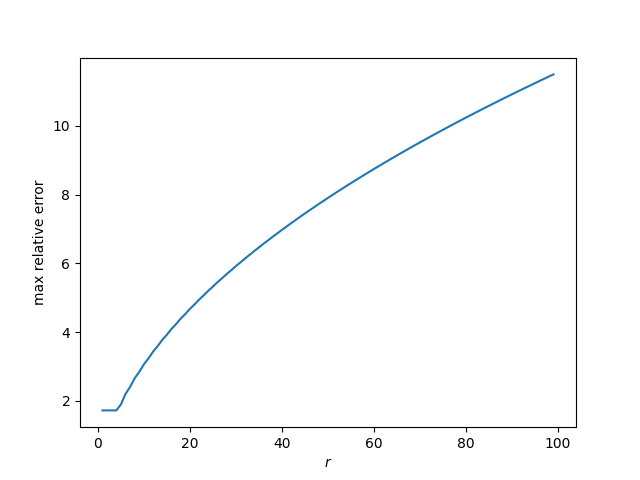
Returning to the original notation C(r, k), let’s see how tight the optimal bound is by plotting, as a function of r, the maximum relative error as a k varies.

The maximum relative error, over the range plotted, is very roughly r/10.

Related posts

[1] Grzegorz Łysik. The ε-binomial inequality. The Mathematical Gazette. Vol. 92, No. 523 (March 2008), pp. 97–99

A couple more variations on an ancient theme

I’ve written a couple posts on the approximation

\cos x \approx \frac{\pi^2 - 4x^2}{\pi^2 + x^2}

by the Indian astronomer Aryabhata (476–550). The approximation is accurate for x in [−π/2, π/2].

The first post collected a Twitter thread about the approximation into a post. The second looked at how far the coefficients in Aryabhata’s approximation are from the optimal approximation as a ratio of quadratics.

This post will answer a couple questions. First, what value of π did Aryabhata have and how would that effect the approximation error? Second, how bad would Aryabhata’s approximation be if we used the approximation π² ≈ 10?

Using Aryabhata’s value of π

Aryabhata knew the value 3.1416 for π. We know this because he said that a circle of diameter 20,000 would have circumference  62,832. We don’t know, but it’s plausible that he knew π to more accuracy and rounded it to the implied value.

Substituting 3.1416 for π changes the sixth decimal of the approximation, but the approximation is good to only three decimal places, so 3.1416 is as good as a more accurate approximation as far as the error in approximating cosine is concerned.

Using π² ≈ 10

Substituting 10 for π² in Aryabhata’s approximation gives an approximation that’s convenient to evaluate by hand.

\cos x \approx \frac{10 - 4x^2}{10 + x^2}

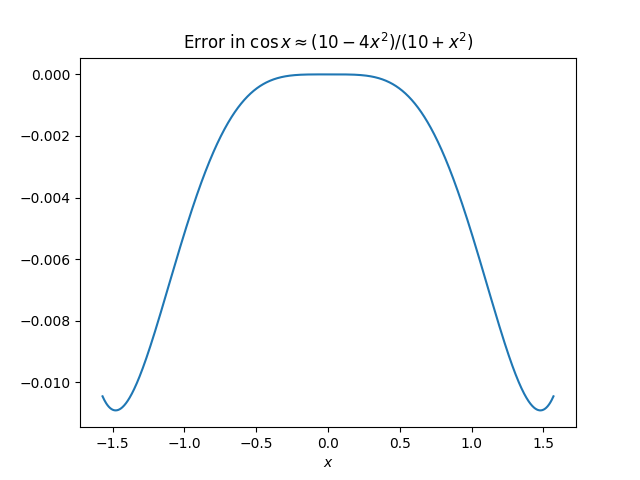
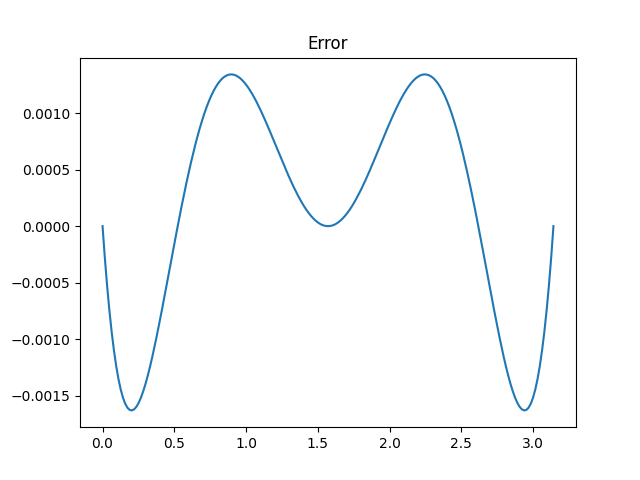
It’s very accurate for small values of x but the maximum error increases from 0.00163 to 0.01091. Here’s a plot of the error.

Finding pi in the alphabet

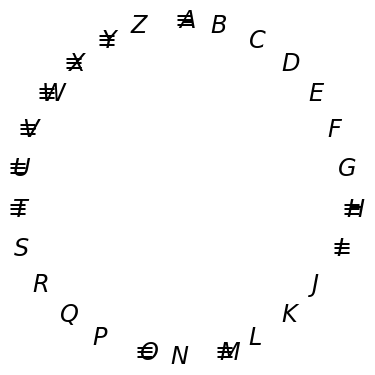
Write the letters of the alphabet around a circle, then strike out the letters that are symmetrical about a vertical line. The remaining letters are grouped in clumps of 3, 1, 4, 1, and 6 letters.

I’ve heard that this observation is due to Martin Gardner, but I don’t have a specific reference.

In case you’re interested, here’s the Python script I wrote to make the image above.

    from numpy import *
    import matplotlib.pyplot as plt
    
    for i in range(26):
        letter = chr(ord('A') + i)
        if letter in "AHIMOTUVWXY":
            latex = r"$\equiv\!\!\!\!\!" + letter + "$"
        else:
            latex = f"${letter}$"
        theta = pi/2 - 2*pi*i/26
        pt = (0.5*cos(theta), 0.5*sin(theta))
        plt.plot(pt[0], pt[1], ' ')
        plt.annotate(latex, pt, fontsize="xx-large")
    plt.axis("off")
    plt.gca().set_aspect("equal")
    plt.savefig("alphabet_pi.png")

Ancient accurate approximation for sine

This post started out as a Twitter thread. The text below is the same as that of the thread after correcting an error in the first part of the thread. I also added a footnote on a theorem the thread alluded to.

***

The following approximation for sin(x) is remarkably accurate for 0 < x < π.

\sin(x) \approx \frac{16x(\pi - x)}{5\pi^2 - 4x(\pi - x)}

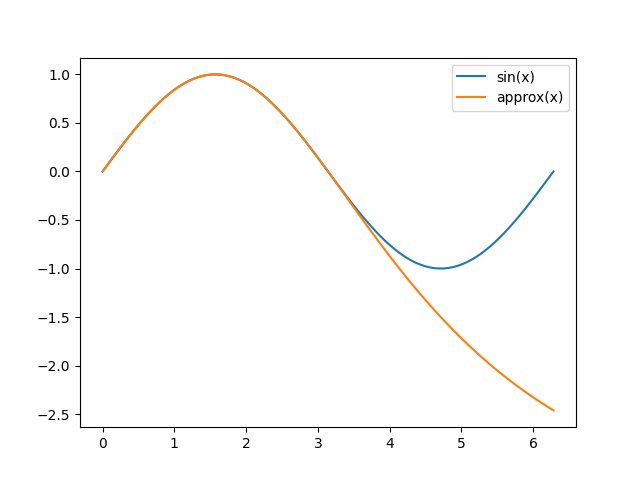
The approximation is so good that you can’t see the difference between the exact value and the approximation until you get outside the range of the approximation.

Here’s a plot of just the error.

This is a very old approximation, dating back to Aryabhata I, around 500 AD.

In modern terms, it is a rational approximation, quadratic in the numerator and denominator. It’s not quite optimal since the ripples in the error function are not of equal height [1], but the coefficients are nice numbers.

***

As pointed out in the comments, replacing x with π/2 − x in order to get an approximation for cosine gives a much nicer equation.

\cos x \approx \frac{\pi^2 - 4x^2}{\pi^2 + x^2}

***

[1] The equioscillation theorem says that the optimal approximation will have ripples of equal positive and negative amplitude. This post explores the equioscillation theorem further and finds how far Aryabhata’s is from optimal.